Unsloth Ministral 3 3B (2512)
server model id:
unsloth/ministral-3-3b-instruct-2512non-thinkingKV Q4_0ctx 32k3B params
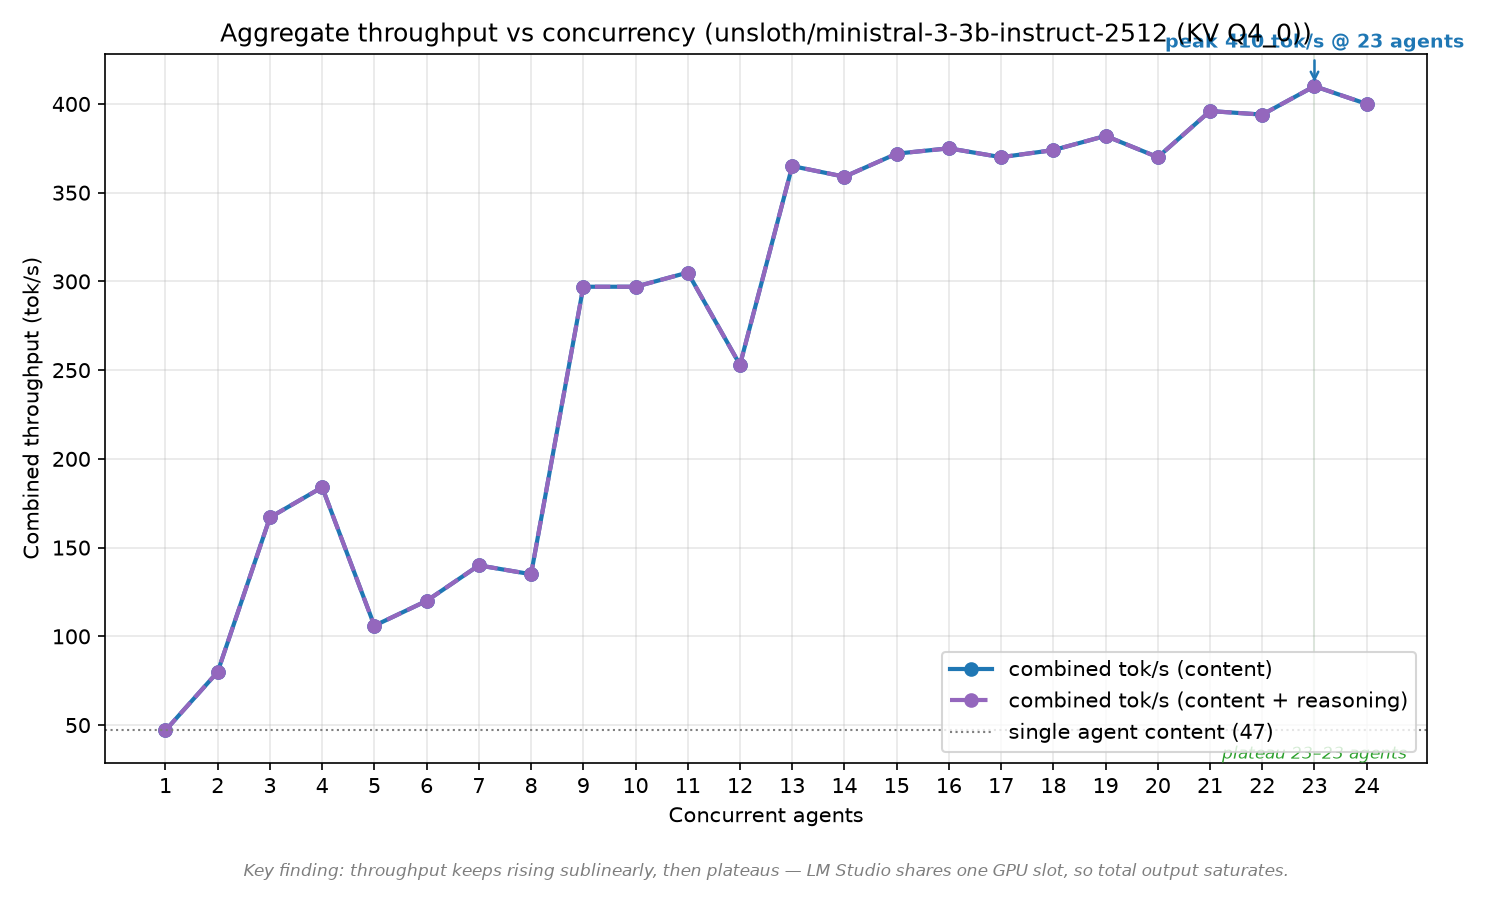
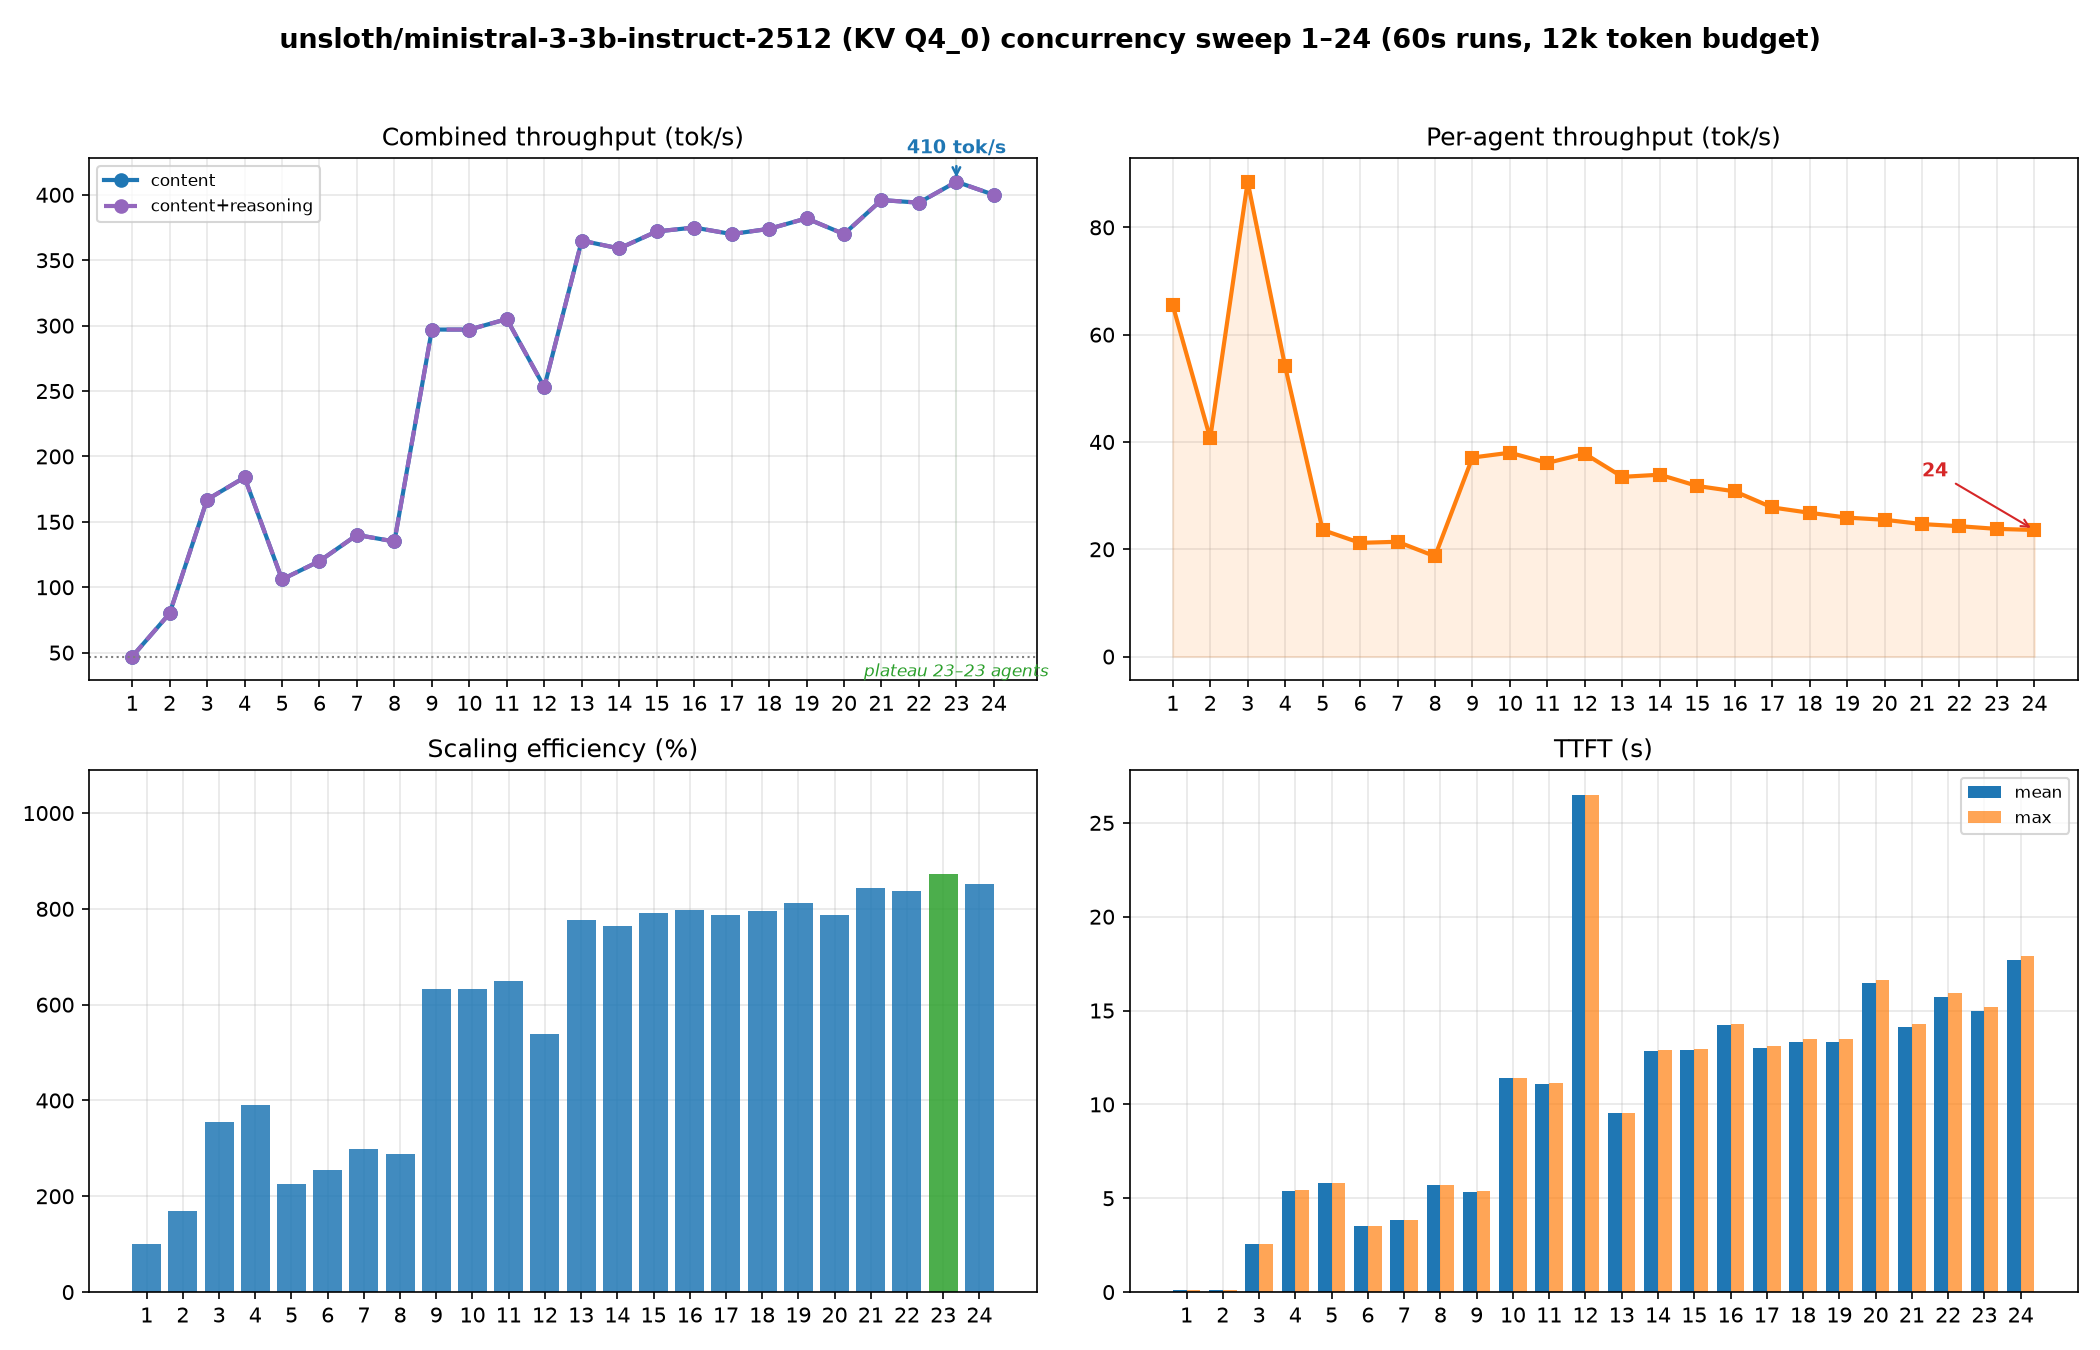
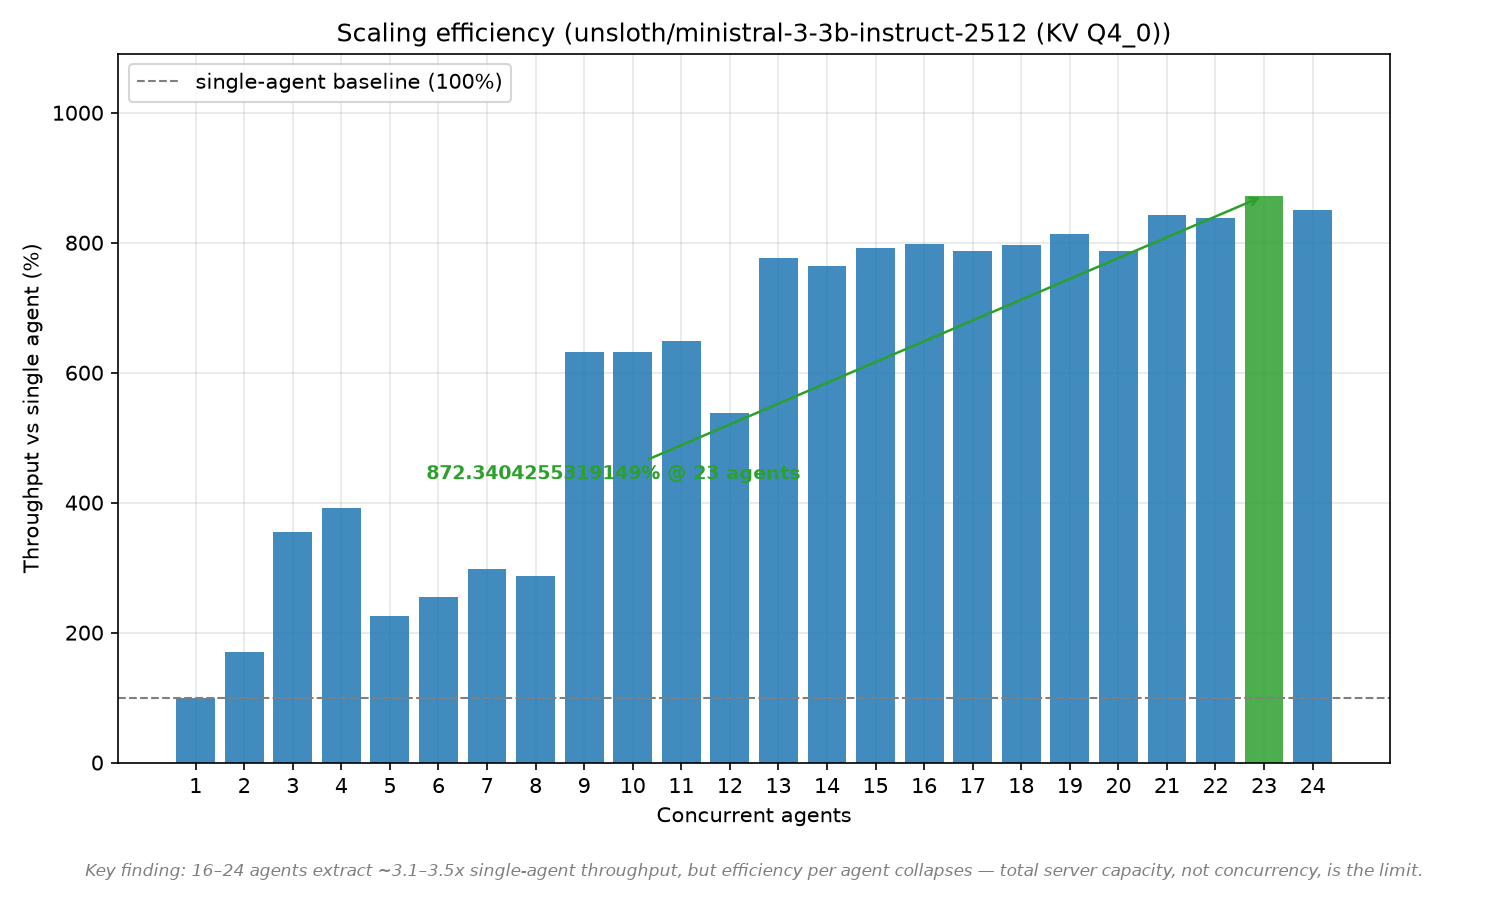
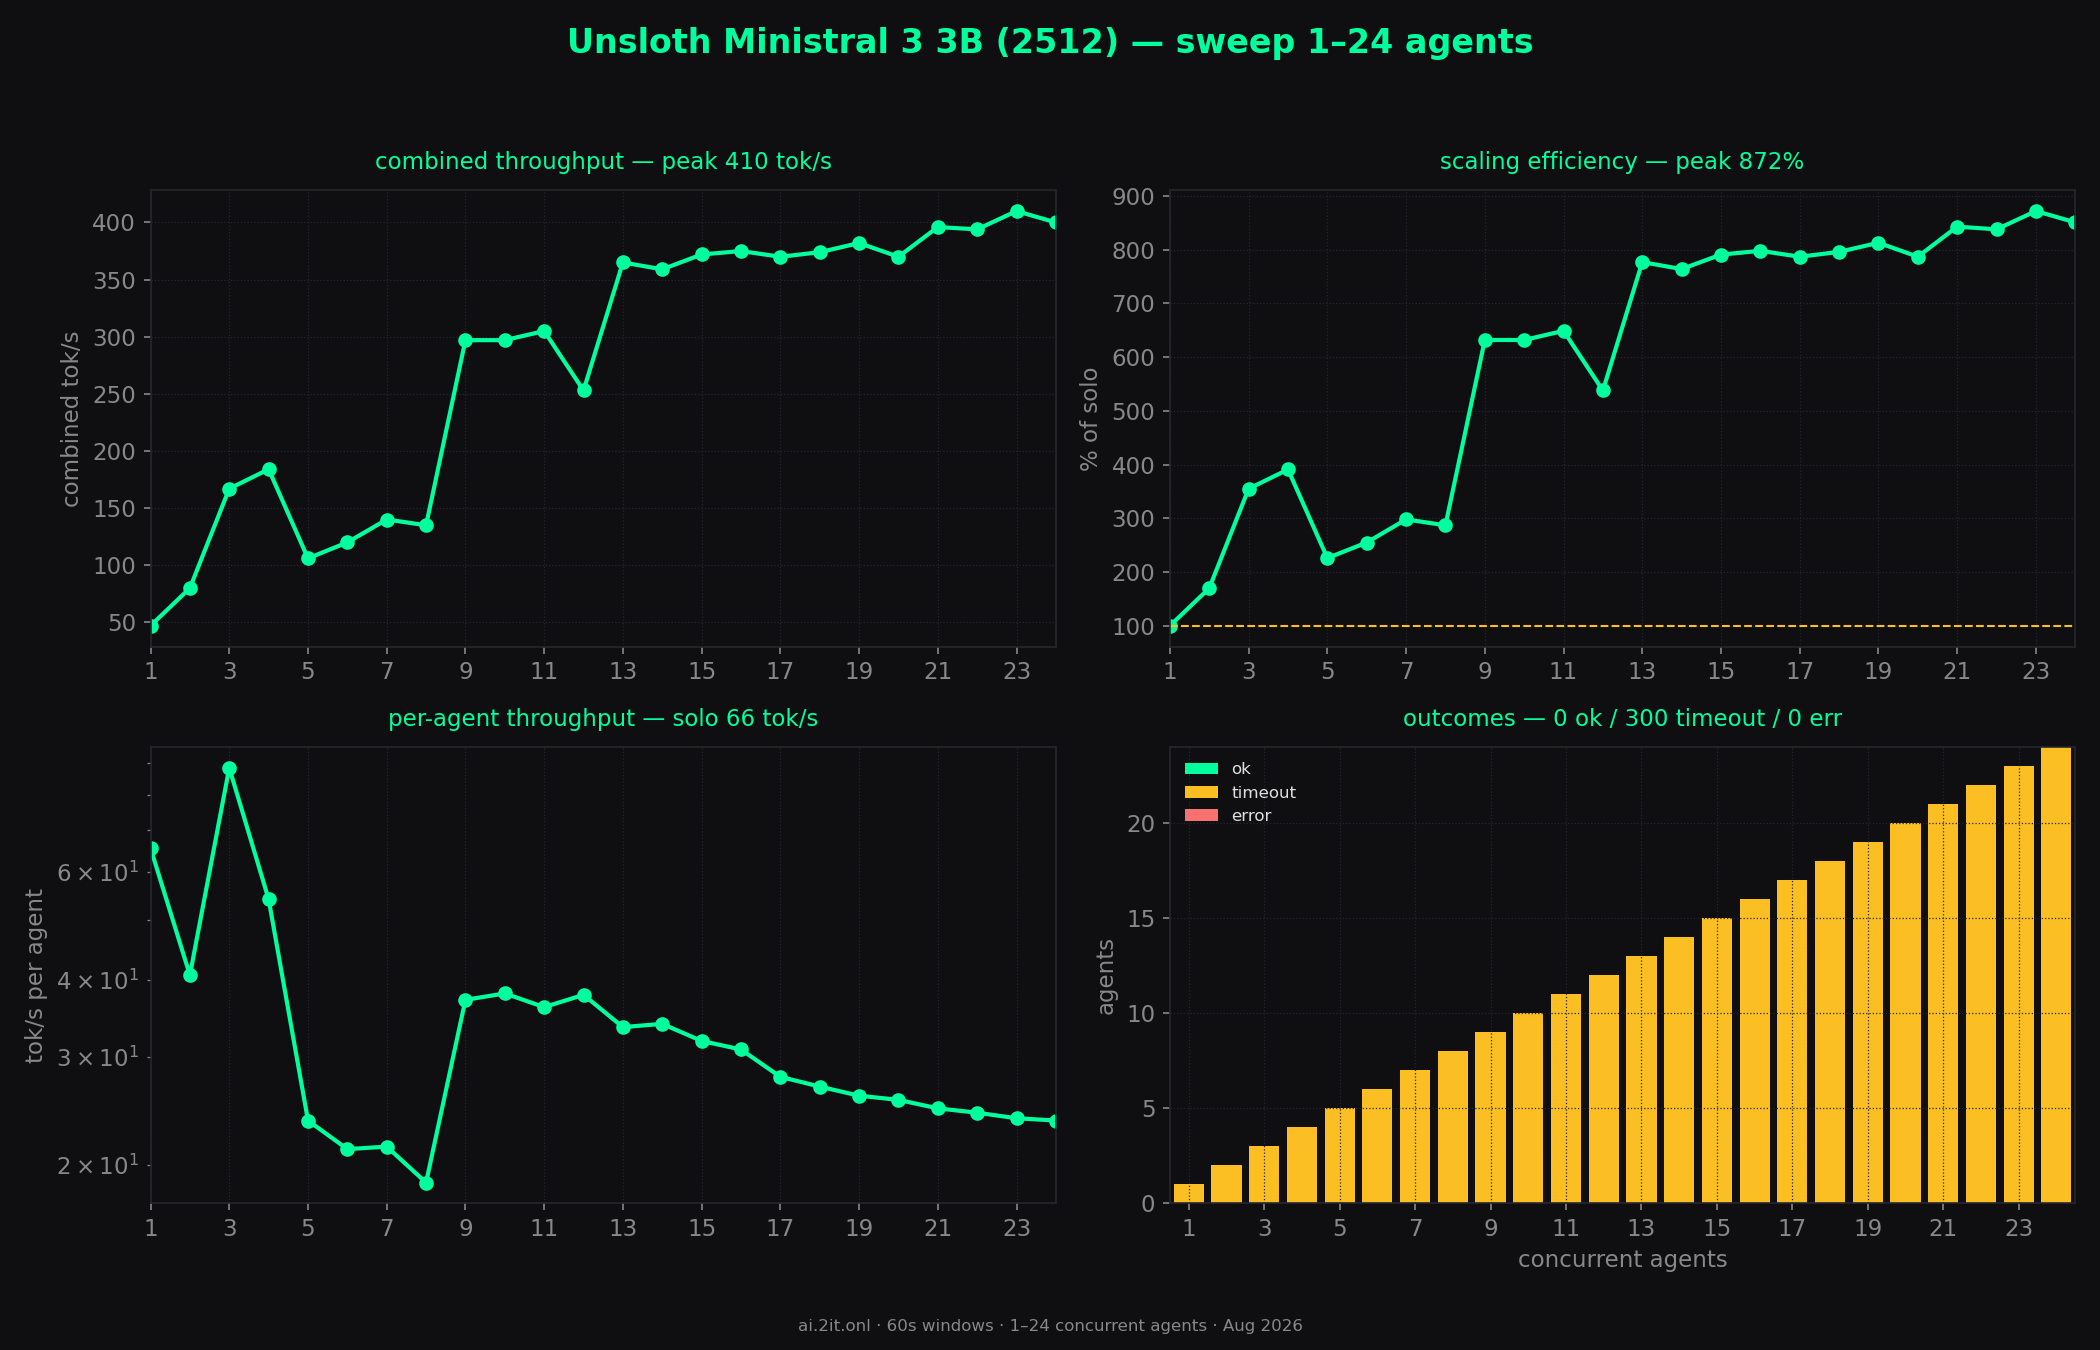
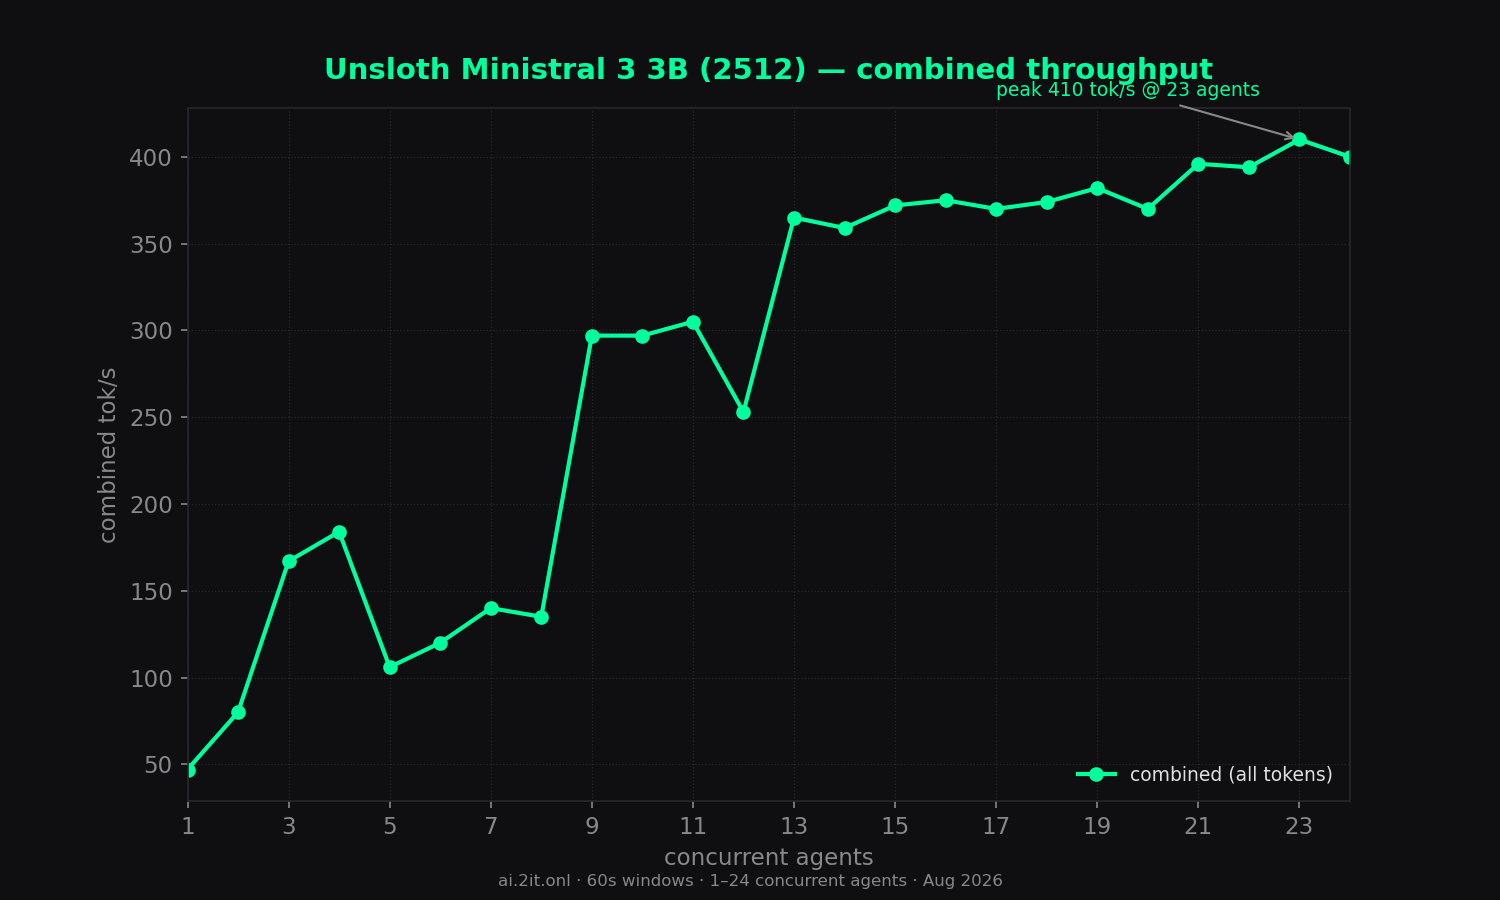
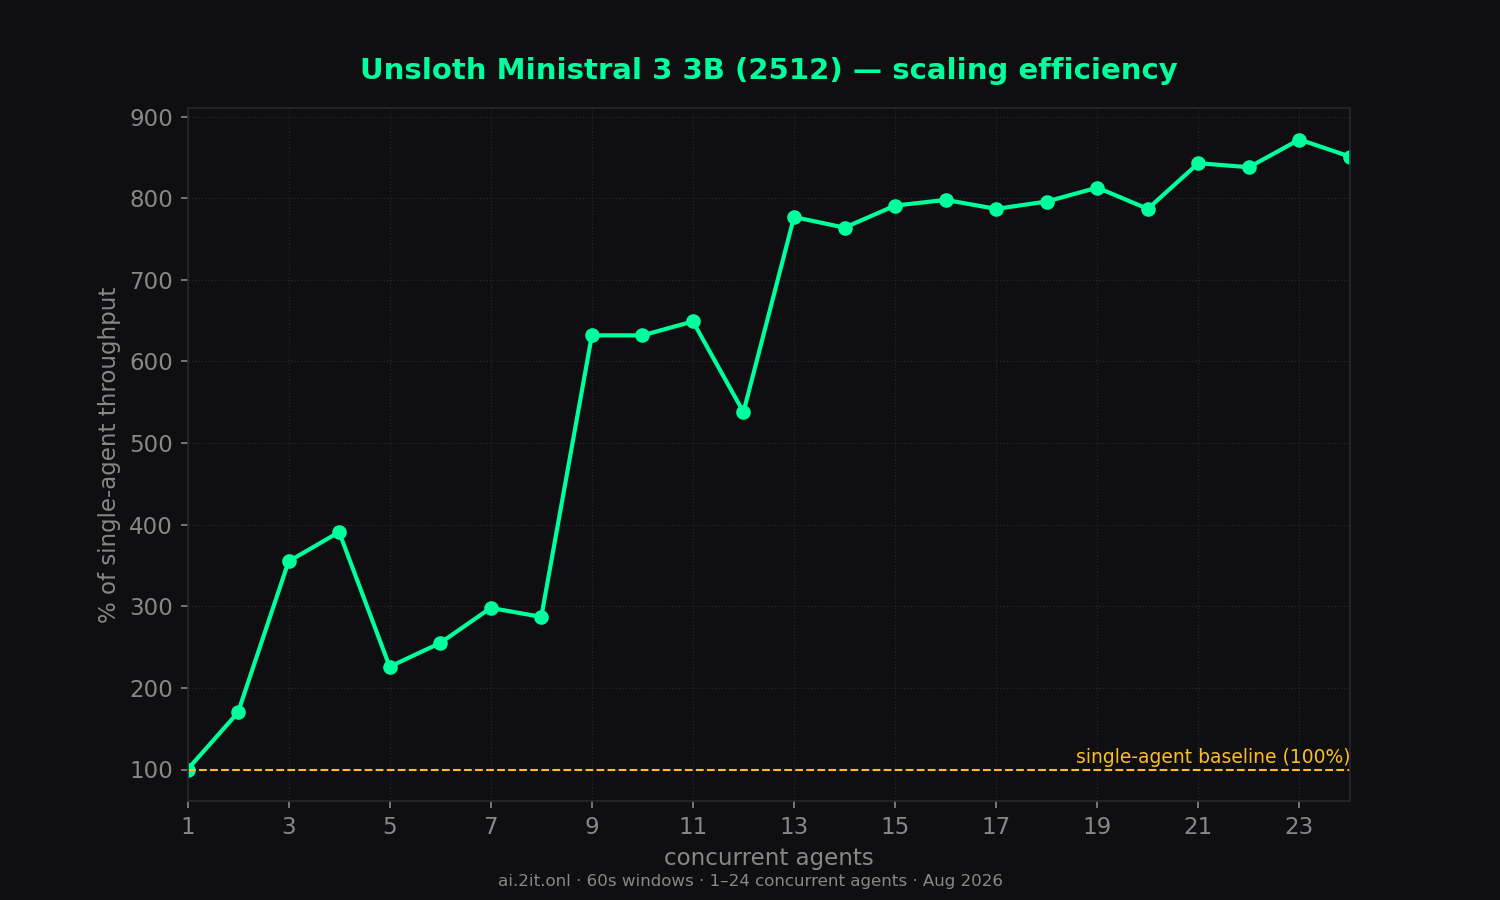
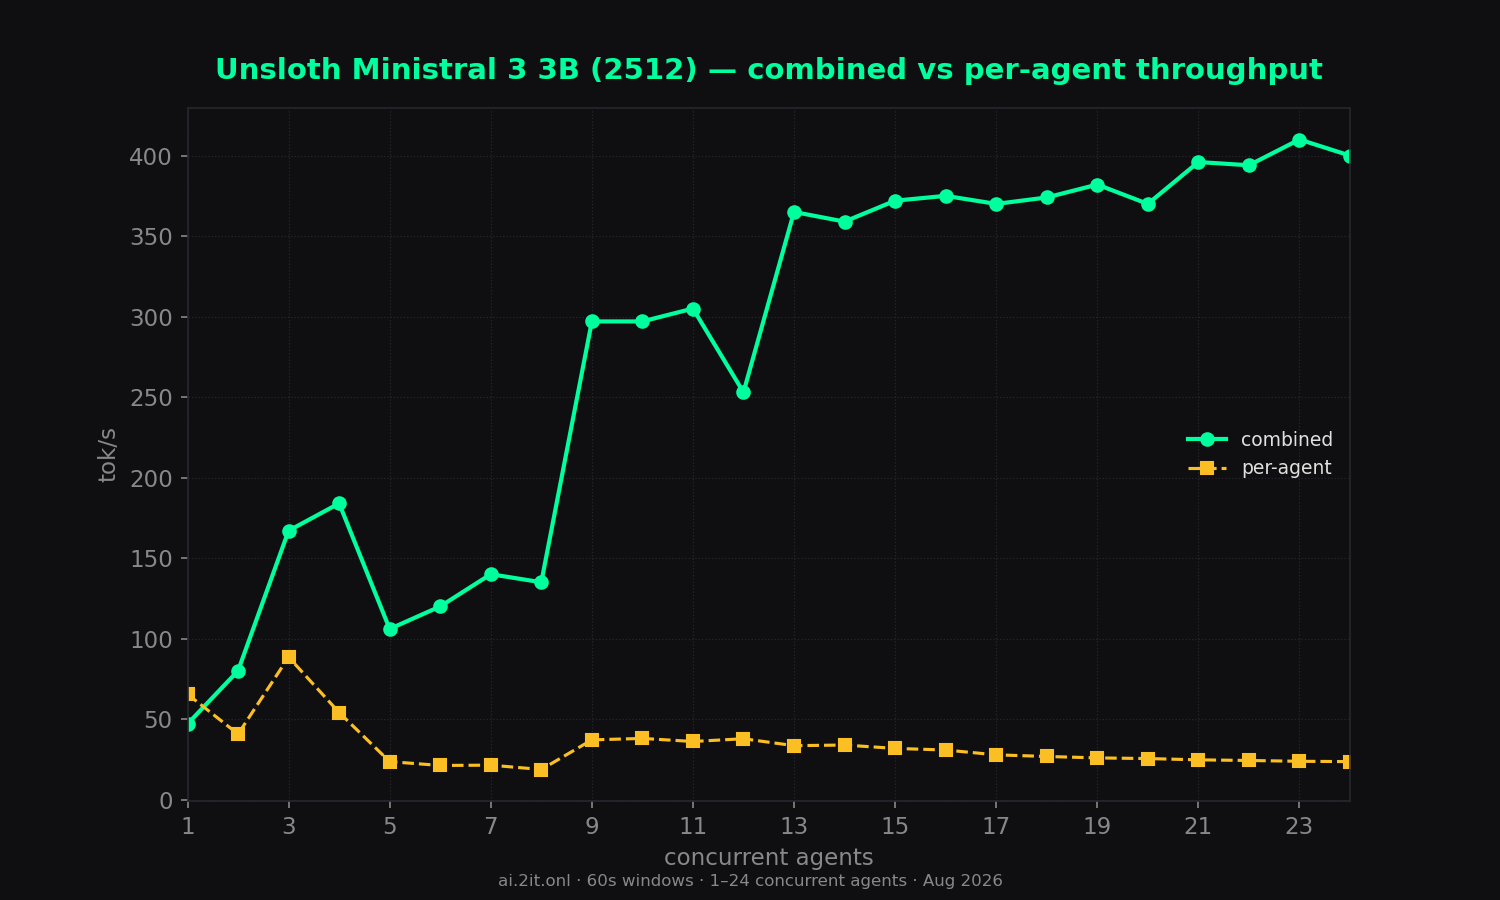
Slowest solo of any model tested (47 tok/s on Q4_0 KV) but the highest relative scaling on record — 8.7x to 410 tok/s at 23 agents.
Key findings
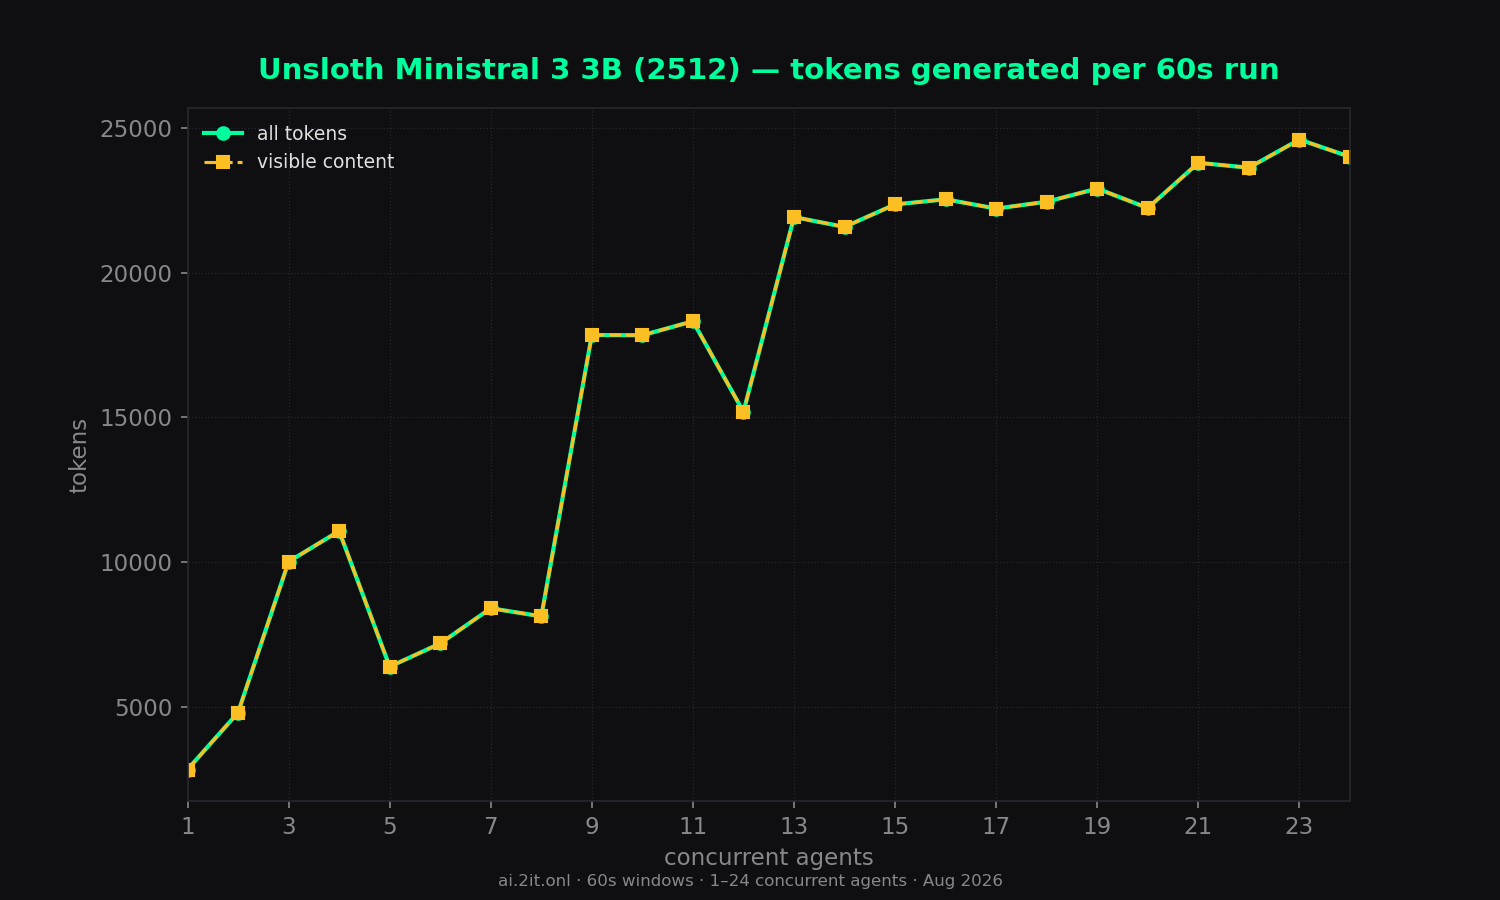
- Clean, all-content output: 0 reasoning tokens everywhere.
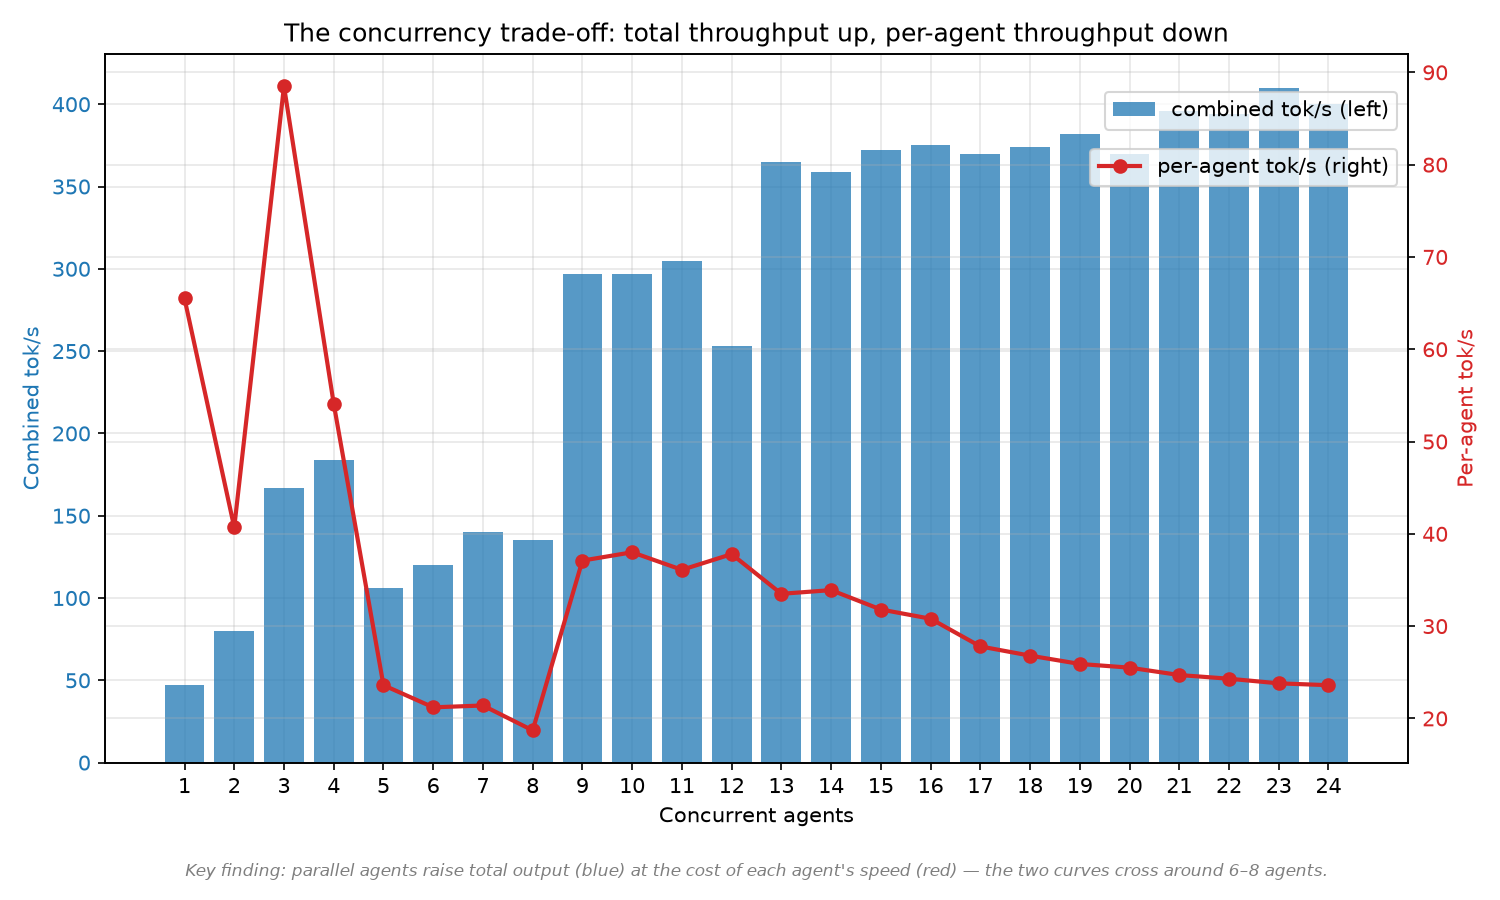
- Slowest single-agent of every model tested: only 47 tok/s at 1 agent — notably slower than granite-4.1-3b (79), chronos (88), and llama-3.2-3b (95). With the Q4_0 KV quant, the KV cache path is 4-bit; on this setup that quant appears to hurt rather than help single-stream speed.
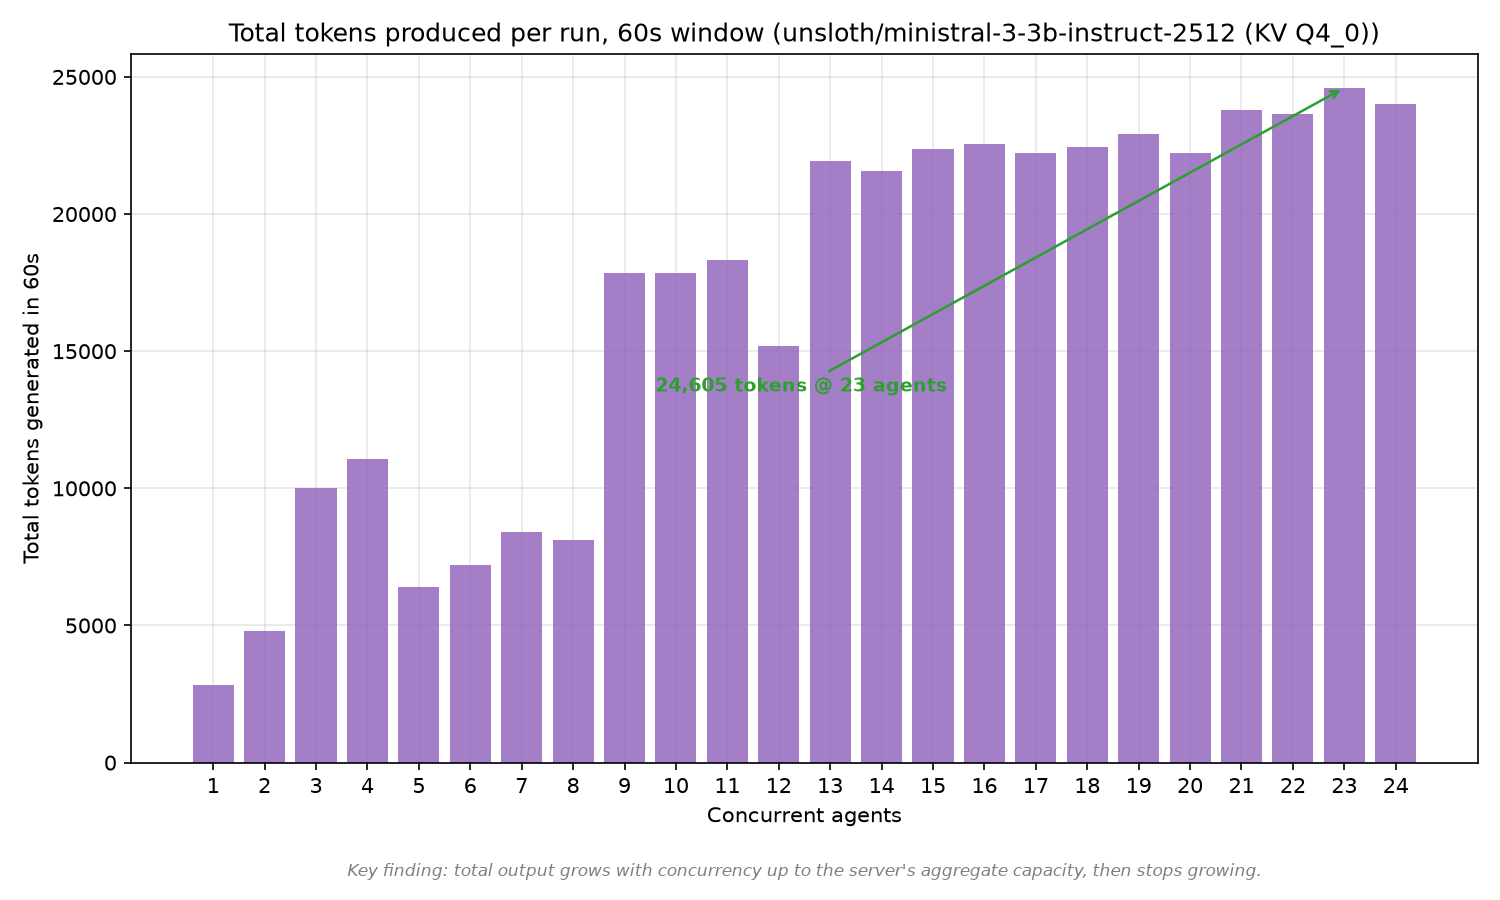
- Giant relative scaling (highest recorded): combined climbs to 410 tok/s at 23 agents (8.7x) — the largest multiplier of any run — but only because the solo baseline is so tiny. Absolute peak (~375–410 tok/s from 13–24) is still mid-pack vs other models.
- Noisy mid-range: big swings between 5–8 agents (106–184) and the 9–13 transition (297 → 253 → 365), showing erratic server batching behavior for this model.
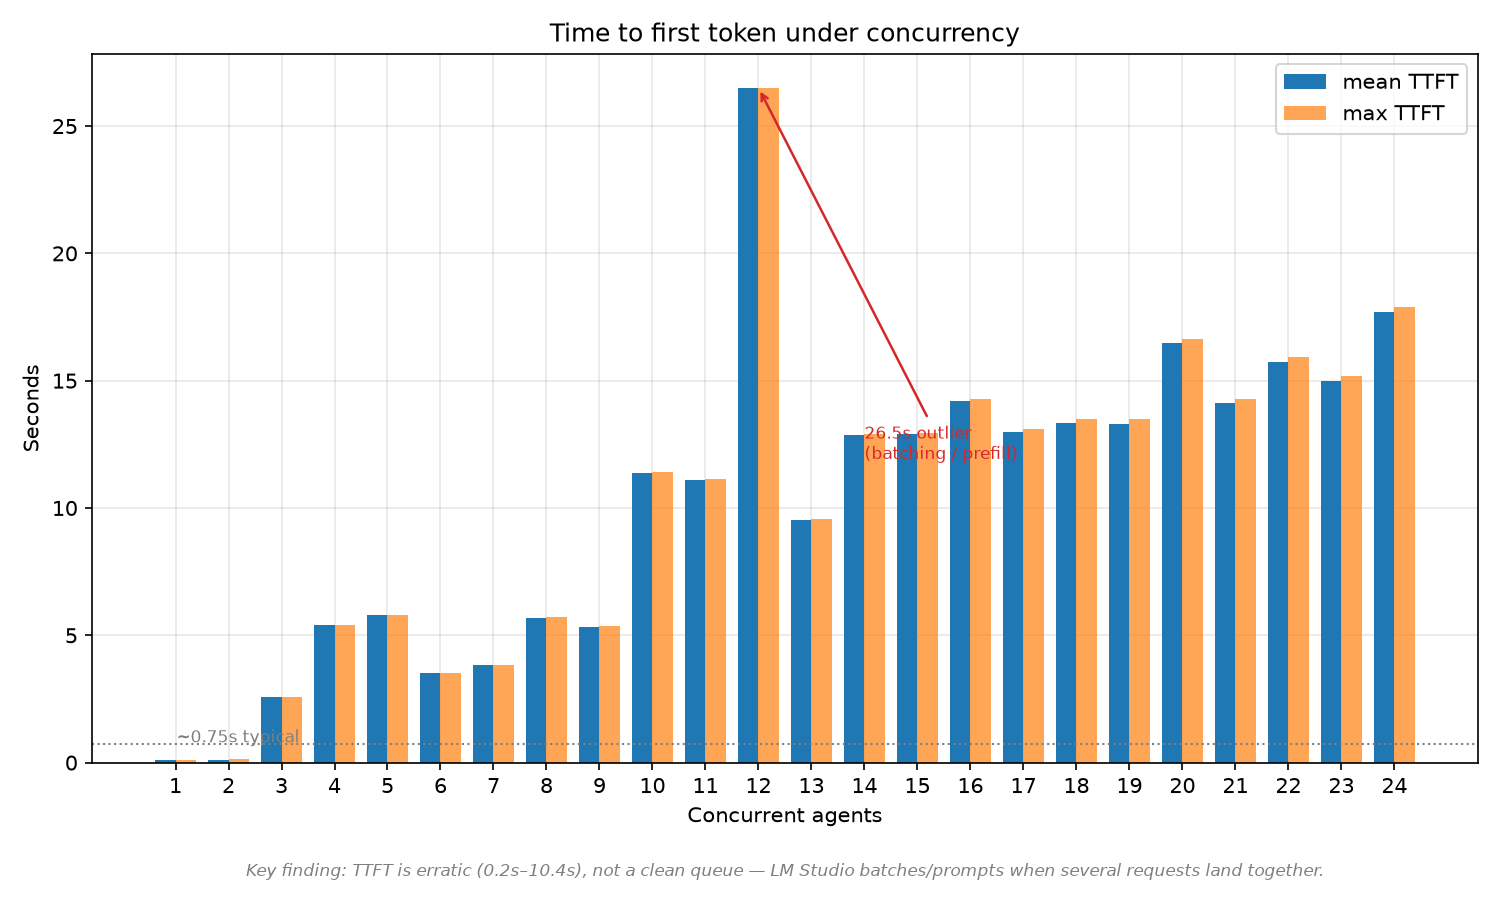
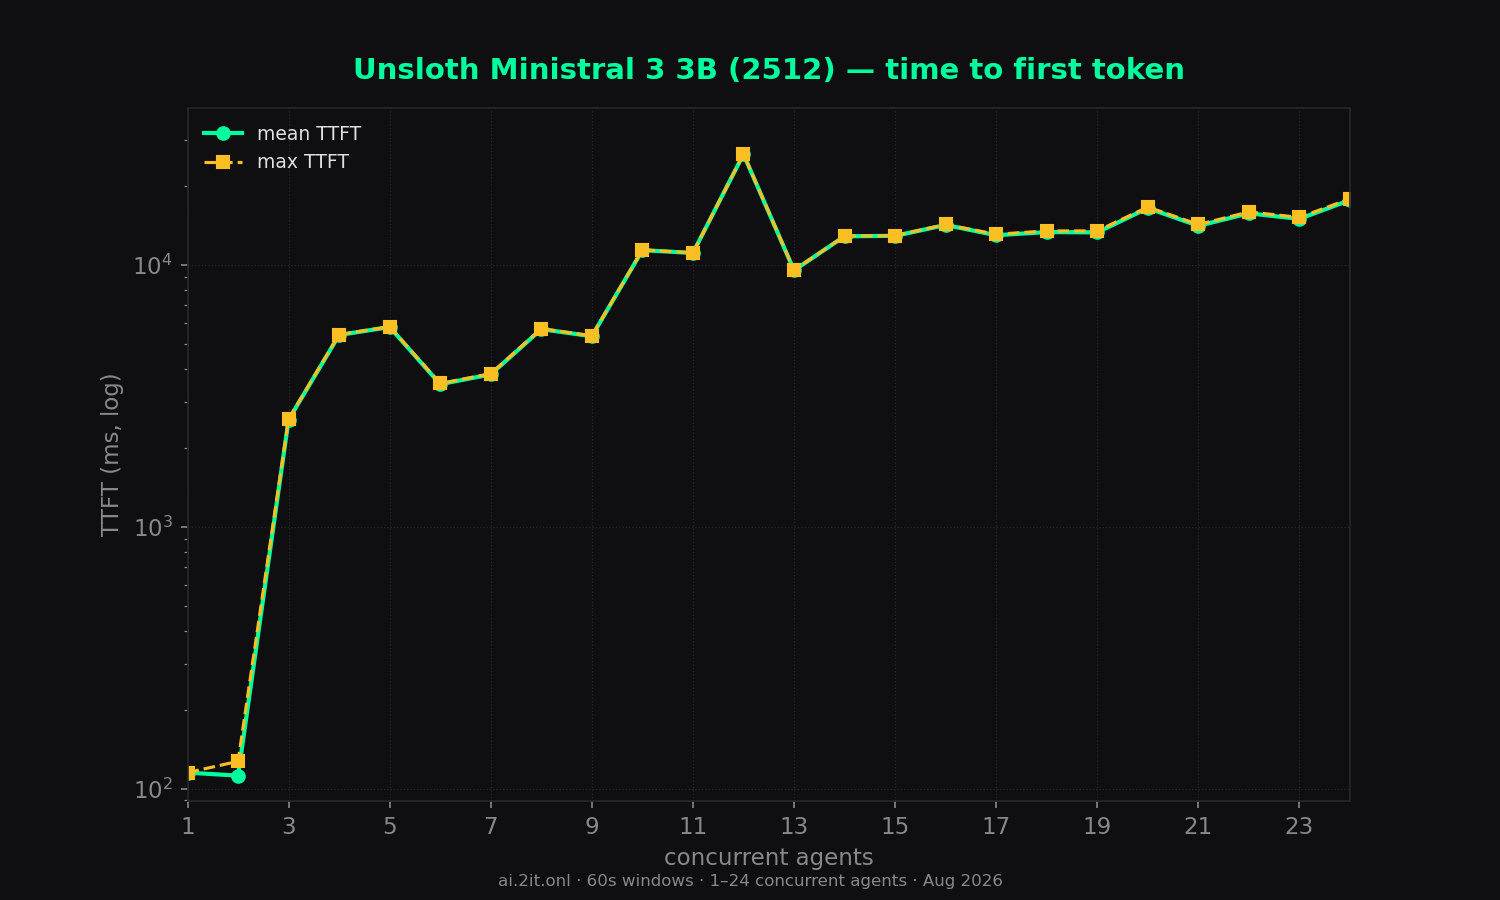
- TTFT: 112ms solo → 17.7s at 24 agents; a ~26.5s outlier at concurrency 12.
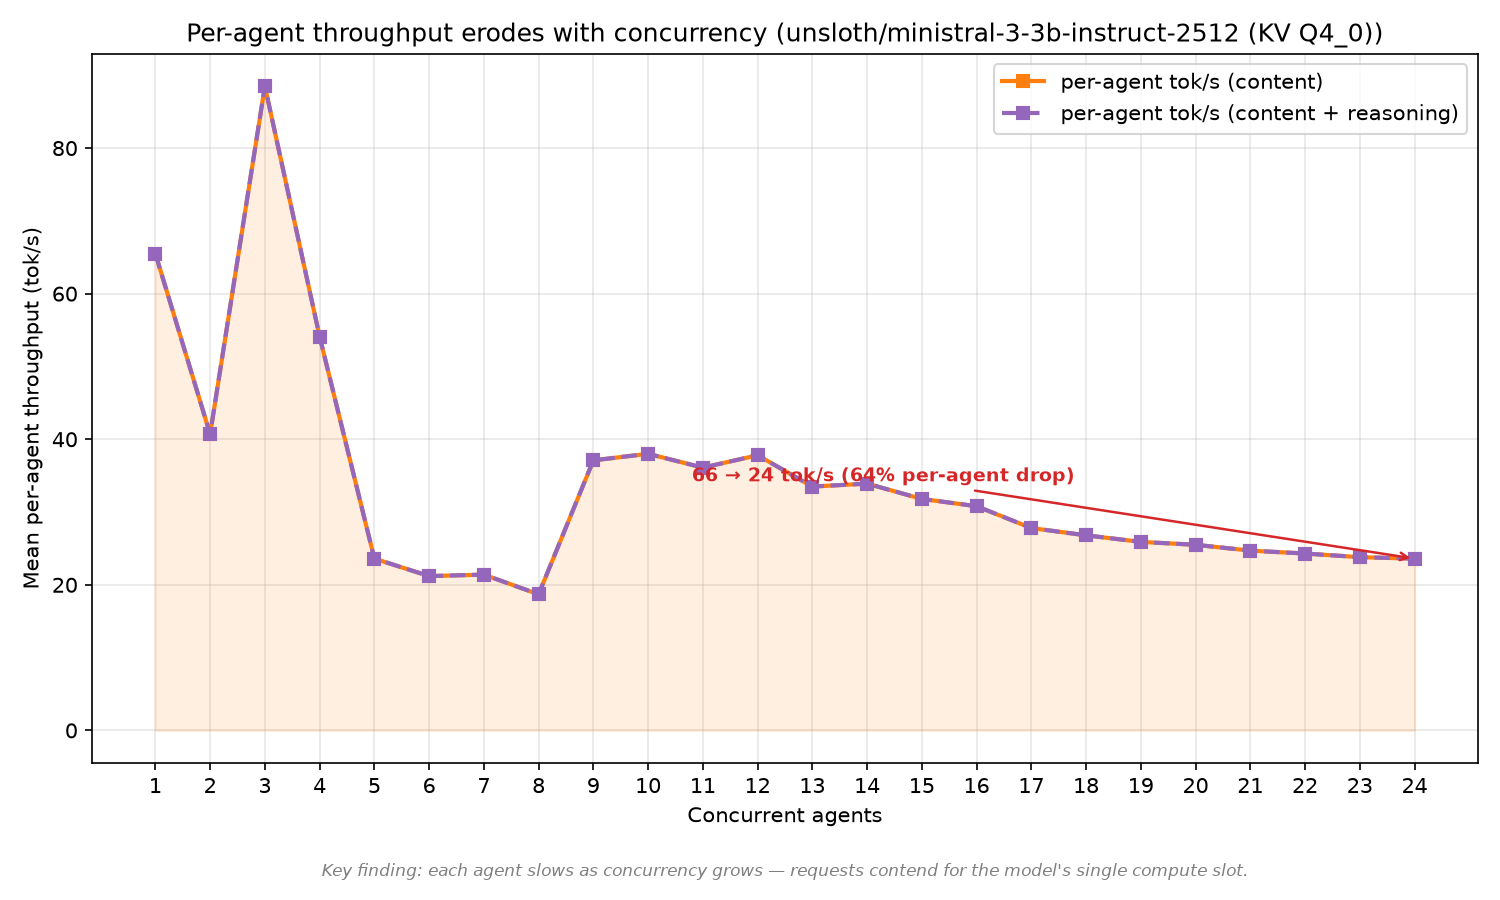
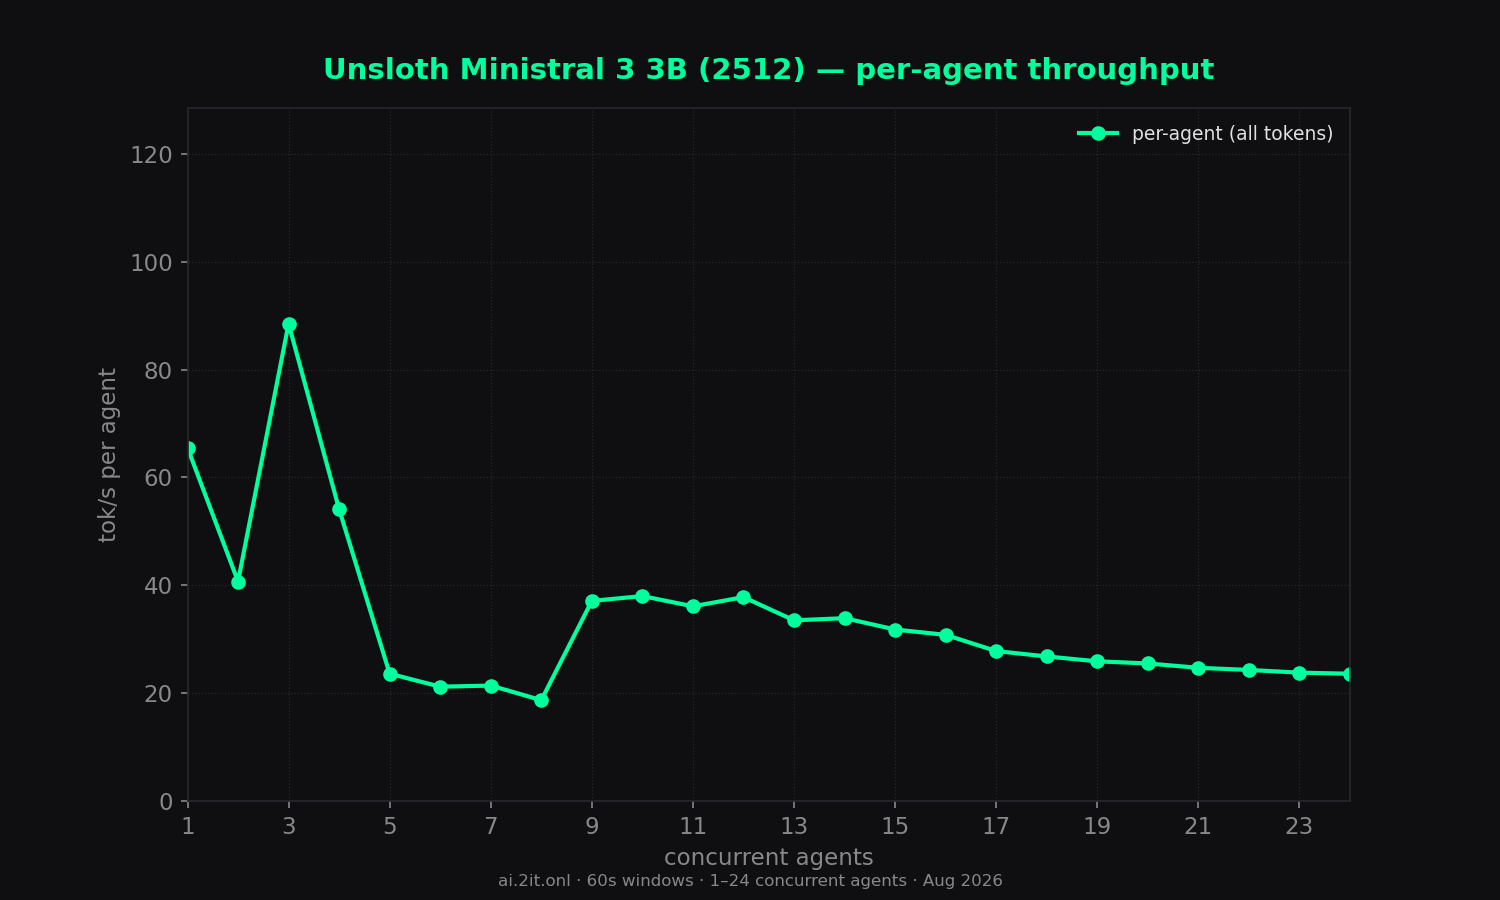
- Per-agent speed: ~24–34 tok/s at high concurrency (vs 65 solo).
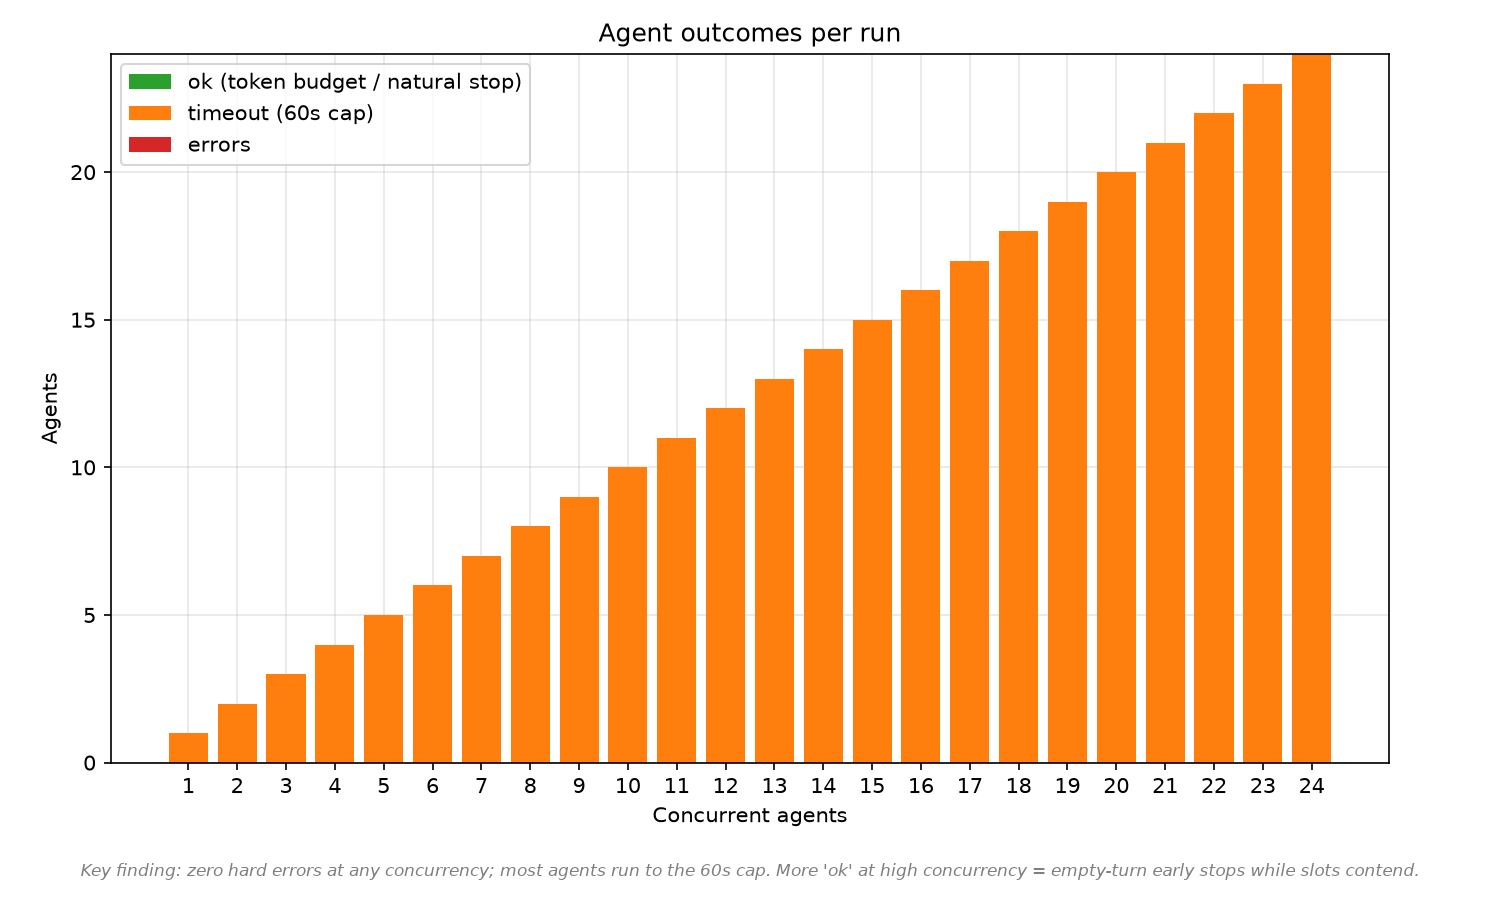
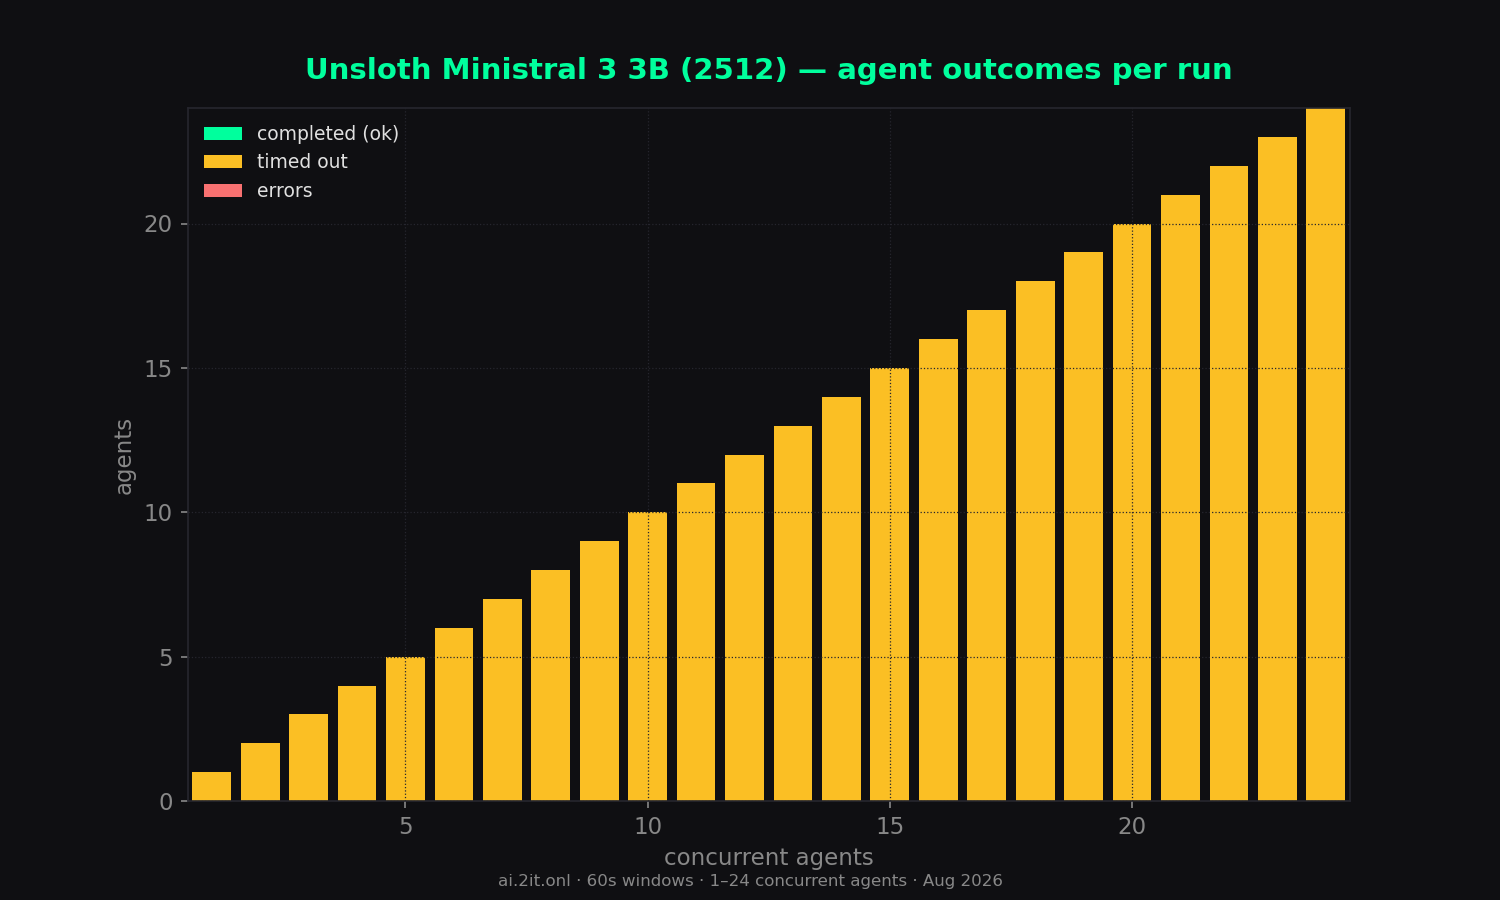
- Errors: 0 across all 24 runs.
Sweep — total concurrency 1–24
| agents | wall (s) | content | reason | total | comb tok/s | comb all | per-agent | per-agent all | scale % | TTFT mean | TTFT max | ok | timeout | err |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 1 | 60.0 | 2,835 | 0 | 2,835 | 47 | 47 | 65.5 | 65.5 | 100% | 115ms | 115ms | 0 | 1 | 0 |
| 2 | 60.0 | 4,799 | 0 | 4,799 | 80 | 80 | 40.7 | 40.7 | 170% | 112ms | 127ms | 0 | 2 | 0 |
| 3 | 60.0 | 10,015 | 0 | 10,015 | 167 | 167 | 88.5 | 88.5 | 355% | 2.6s | 2.6s | 0 | 3 | 0 |
| 4 | 60.0 | 11,075 | 0 | 11,075 | 184 | 184 | 54.1 | 54.1 | 391% | 5.4s | 5.4s | 0 | 4 | 0 |
| 5 | 60.0 | 6,387 | 0 | 6,387 | 106 | 106 | 23.6 | 23.6 | 226% | 5.8s | 5.8s | 0 | 5 | 0 |
| 6 | 60.0 | 7,190 | 0 | 7,190 | 120 | 120 | 21.2 | 21.2 | 255% | 3.5s | 3.5s | 0 | 6 | 0 |
| 7 | 60.0 | 8,407 | 0 | 8,407 | 140 | 140 | 21.4 | 21.4 | 298% | 3.8s | 3.8s | 0 | 7 | 0 |
| 8 | 60.0 | 8,127 | 0 | 8,127 | 135 | 135 | 18.7 | 18.7 | 287% | 5.7s | 5.7s | 0 | 8 | 0 |
| 9 | 60.0 | 17,849 | 0 | 17,849 | 297 | 297 | 37.1 | 37.1 | 632% | 5.3s | 5.4s | 0 | 9 | 0 |
| 10 | 60.0 | 17,841 | 0 | 17,841 | 297 | 297 | 38.0 | 38.0 | 632% | 11.4s | 11.4s | 0 | 10 | 0 |
| 11 | 60.0 | 18,324 | 0 | 18,324 | 305 | 305 | 36.1 | 36.1 | 649% | 11.1s | 11.1s | 0 | 11 | 0 |
| 12 | 60.0 | 15,193 | 0 | 15,193 | 253 | 253 | 37.8 | 37.8 | 538% | 26.5s | 26.5s | 0 | 12 | 0 |
| 13 | 60.0 | 21,925 | 0 | 21,925 | 365 | 365 | 33.5 | 33.5 | 777% | 9.5s | 9.6s | 0 | 13 | 0 |
| 14 | 60.0 | 21,584 | 0 | 21,584 | 359 | 359 | 33.9 | 33.9 | 764% | 12.9s | 12.9s | 0 | 14 | 0 |
| 15 | 60.0 | 22,363 | 0 | 22,363 | 372 | 372 | 31.8 | 31.8 | 791% | 12.9s | 12.9s | 0 | 15 | 0 |
| 16 | 60.0 | 22,537 | 0 | 22,537 | 375 | 375 | 30.8 | 30.8 | 798% | 14.2s | 14.3s | 0 | 16 | 0 |
| 17 | 60.0 | 22,218 | 0 | 22,218 | 370 | 370 | 27.8 | 27.8 | 787% | 13.0s | 13.1s | 0 | 17 | 0 |
| 18 | 60.0 | 22,455 | 0 | 22,455 | 374 | 374 | 26.8 | 26.8 | 796% | 13.4s | 13.5s | 0 | 18 | 0 |
| 19 | 60.0 | 22,909 | 0 | 22,909 | 382 | 382 | 25.9 | 25.9 | 813% | 13.3s | 13.5s | 0 | 19 | 0 |
| 20 | 60.0 | 22,237 | 0 | 22,237 | 370 | 370 | 25.5 | 25.5 | 787% | 16.5s | 16.6s | 0 | 20 | 0 |
| 21 | 60.0 | 23,800 | 0 | 23,800 | 396 | 396 | 24.7 | 24.7 | 843% | 14.1s | 14.3s | 0 | 21 | 0 |
| 22 | 60.0 | 23,630 | 0 | 23,630 | 394 | 394 | 24.3 | 24.3 | 838% | 15.7s | 15.9s | 0 | 22 | 0 |
| 23 peak | 60.0 | 24,605 | 0 | 24,605 | 410 | 410 | 23.8 | 23.8 | 872% | 15.0s | 15.2s | 0 | 23 | 0 |
| 24 | 60.0 | 24,005 | 0 | 24,005 | 400 | 400 | 23.6 | 23.6 | 851% | 17.7s | 17.9s | 0 | 24 | 0 |
* burst artifact — agents queued ~11–16s then generated in a short burst; the per-agent timer inflates the number. Trust combined throughput and TTFT columns. Peak row = highest combined (all-token) throughput.
Charts
Raw data & downloads
- report.md6 KB
- sweep-summary.csv2 KB
- sweep-summary.json11 KB
- combined_throughput.png124 KB · original matplotlib export
- combined_vs_per_agent.png114 KB · original matplotlib export
- dashboard_1_24.png174 KB · original matplotlib export
- outcome_breakdown.png57 KB · original matplotlib export
- per_agent_throughput.png115 KB · original matplotlib export
- scaling_efficiency.png83 KB · original matplotlib export
- time_to_first_token.png65 KB · original matplotlib export
- total_tokens_generated.png75 KB · original matplotlib export