MiniCPM5 1B ×2 (parallel)
server model id:
minicpm5-1b-claude-opus-fable5-v2-thinking / -22× parallel instancesthinkingKV F16ctx 32k1B params
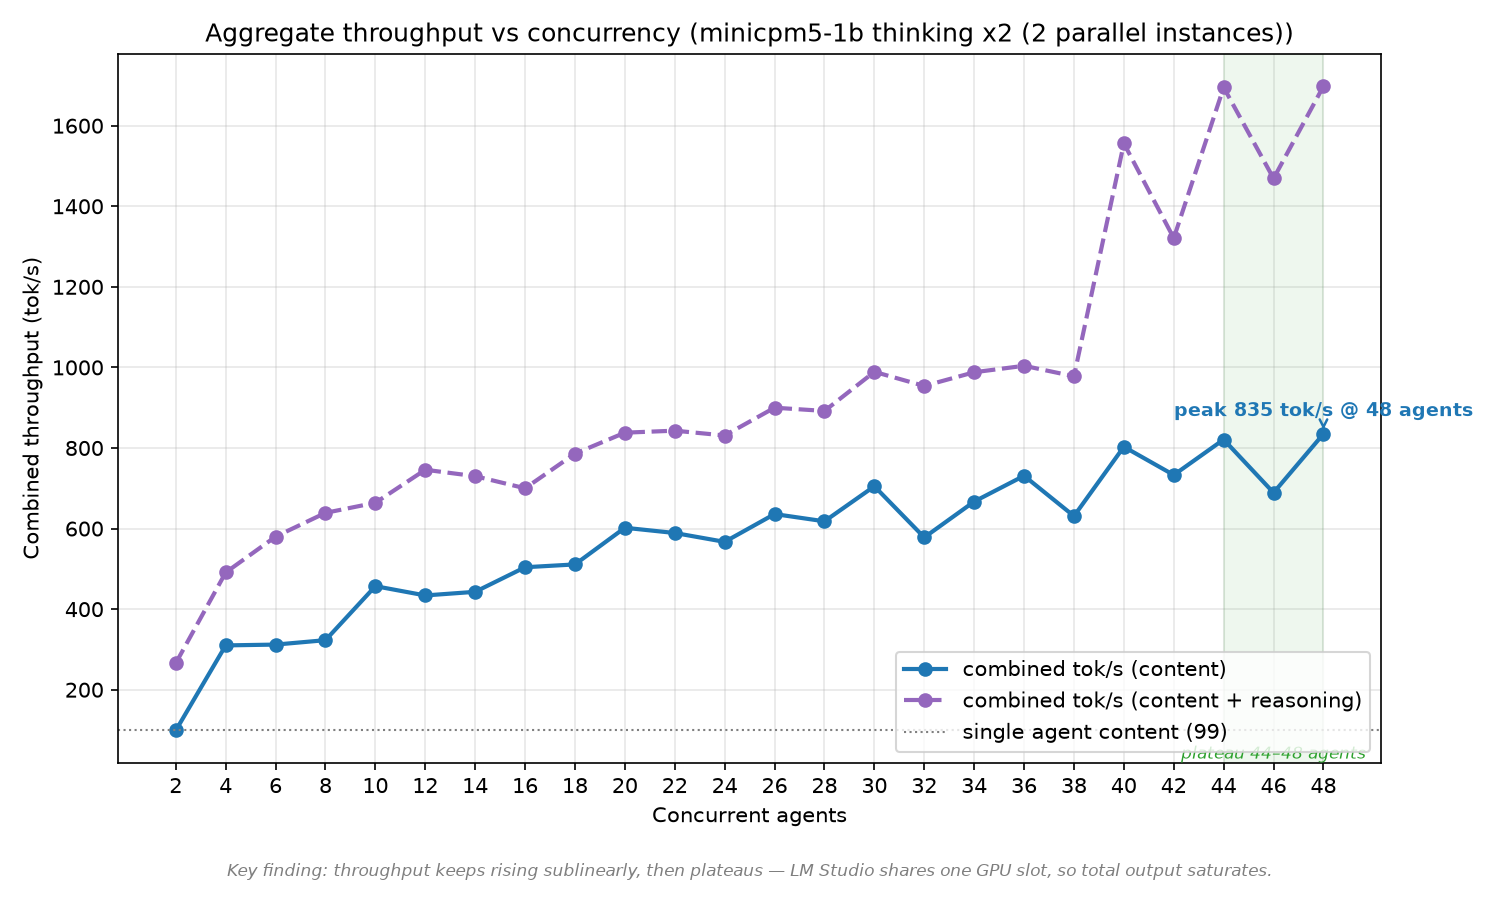
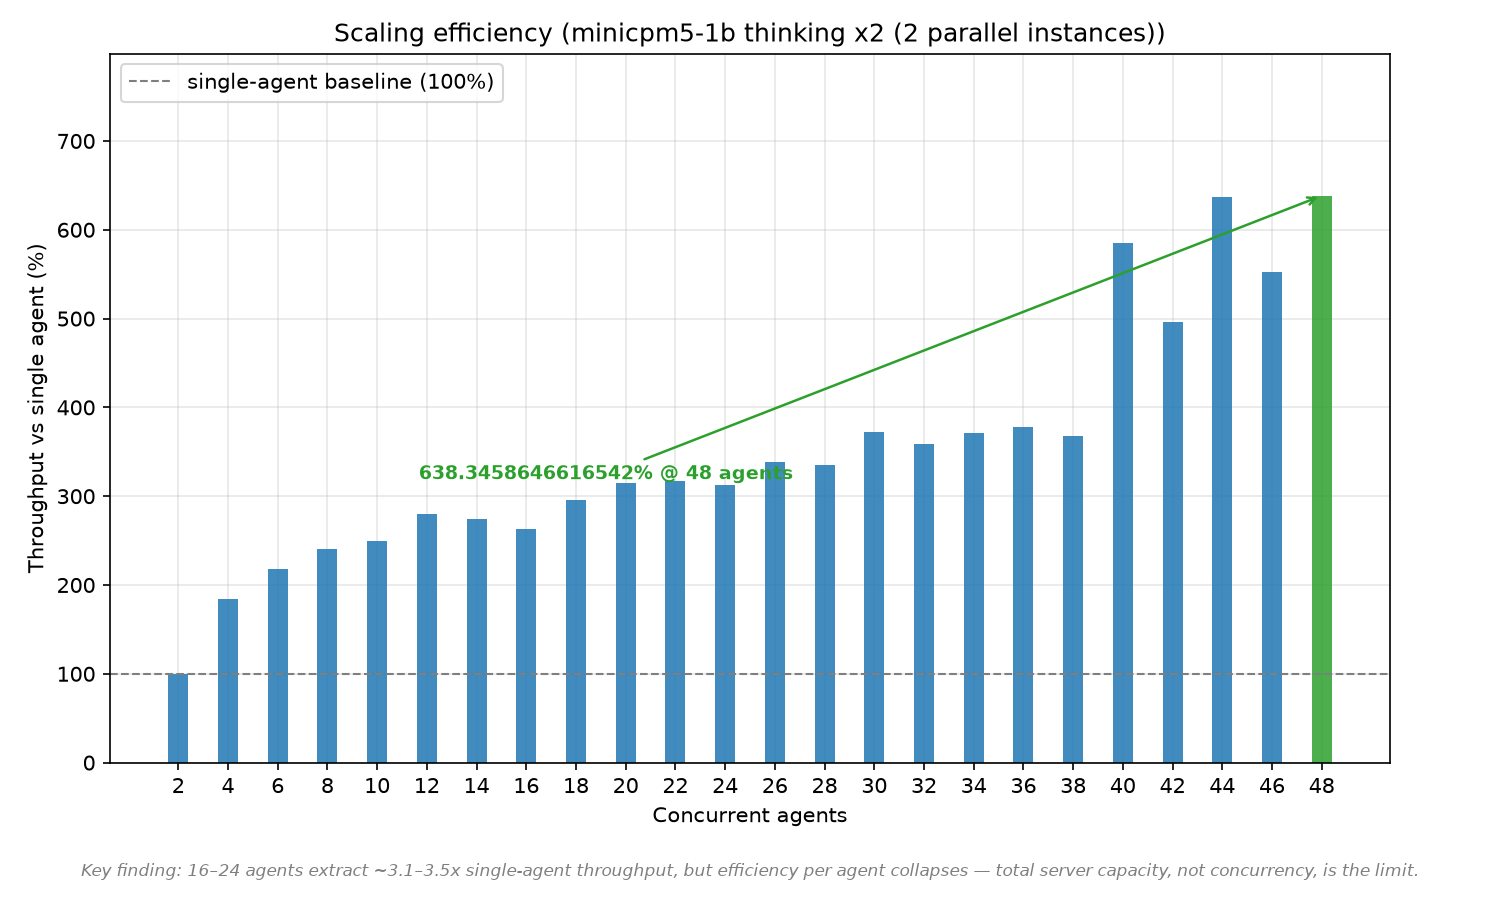
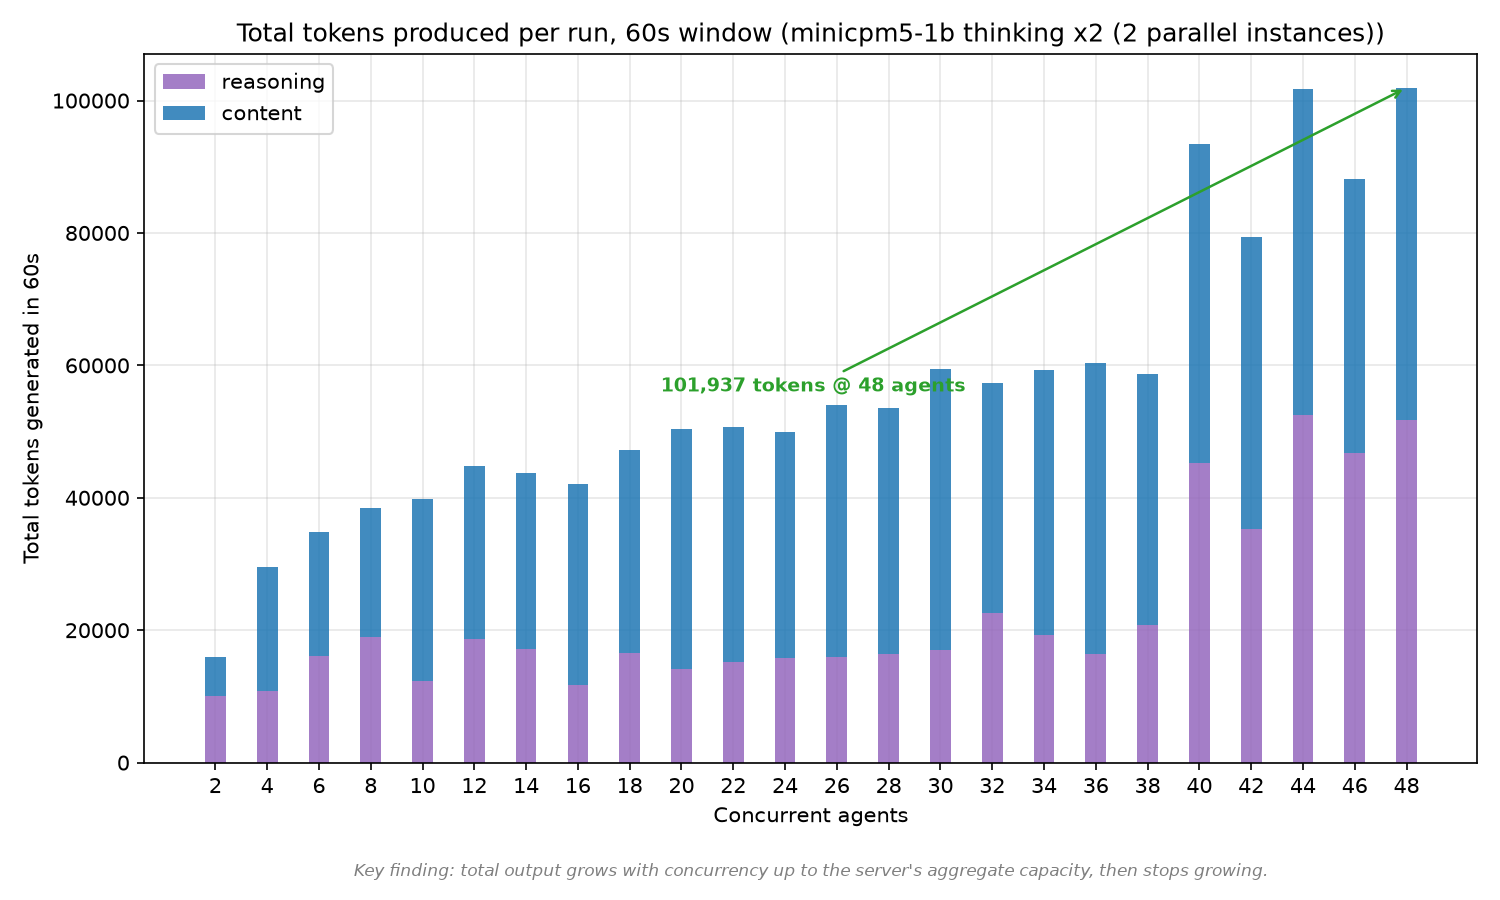
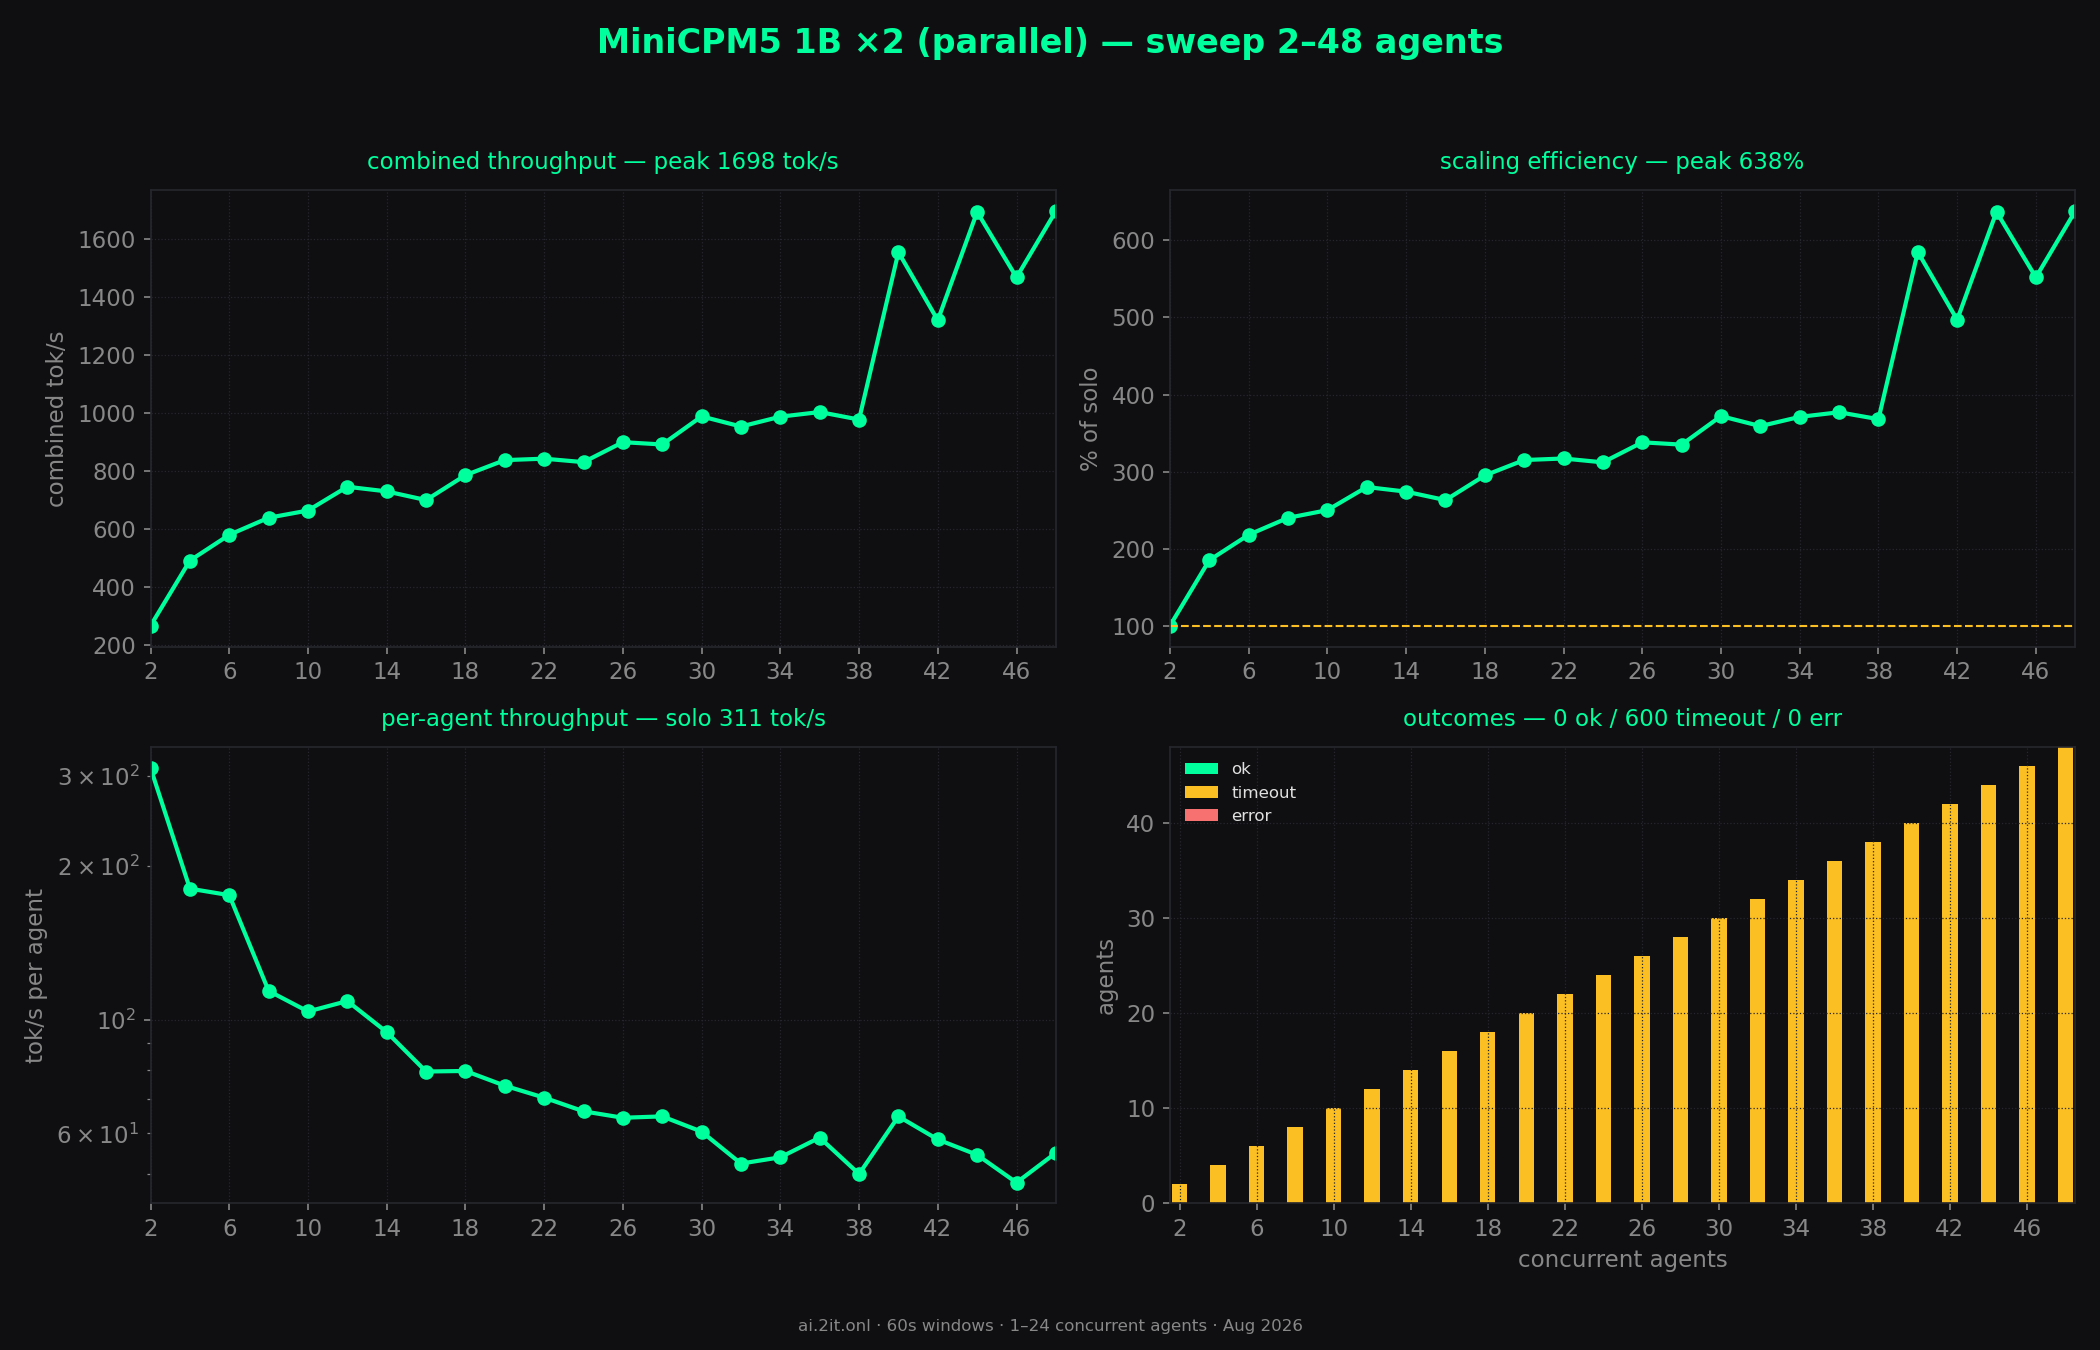
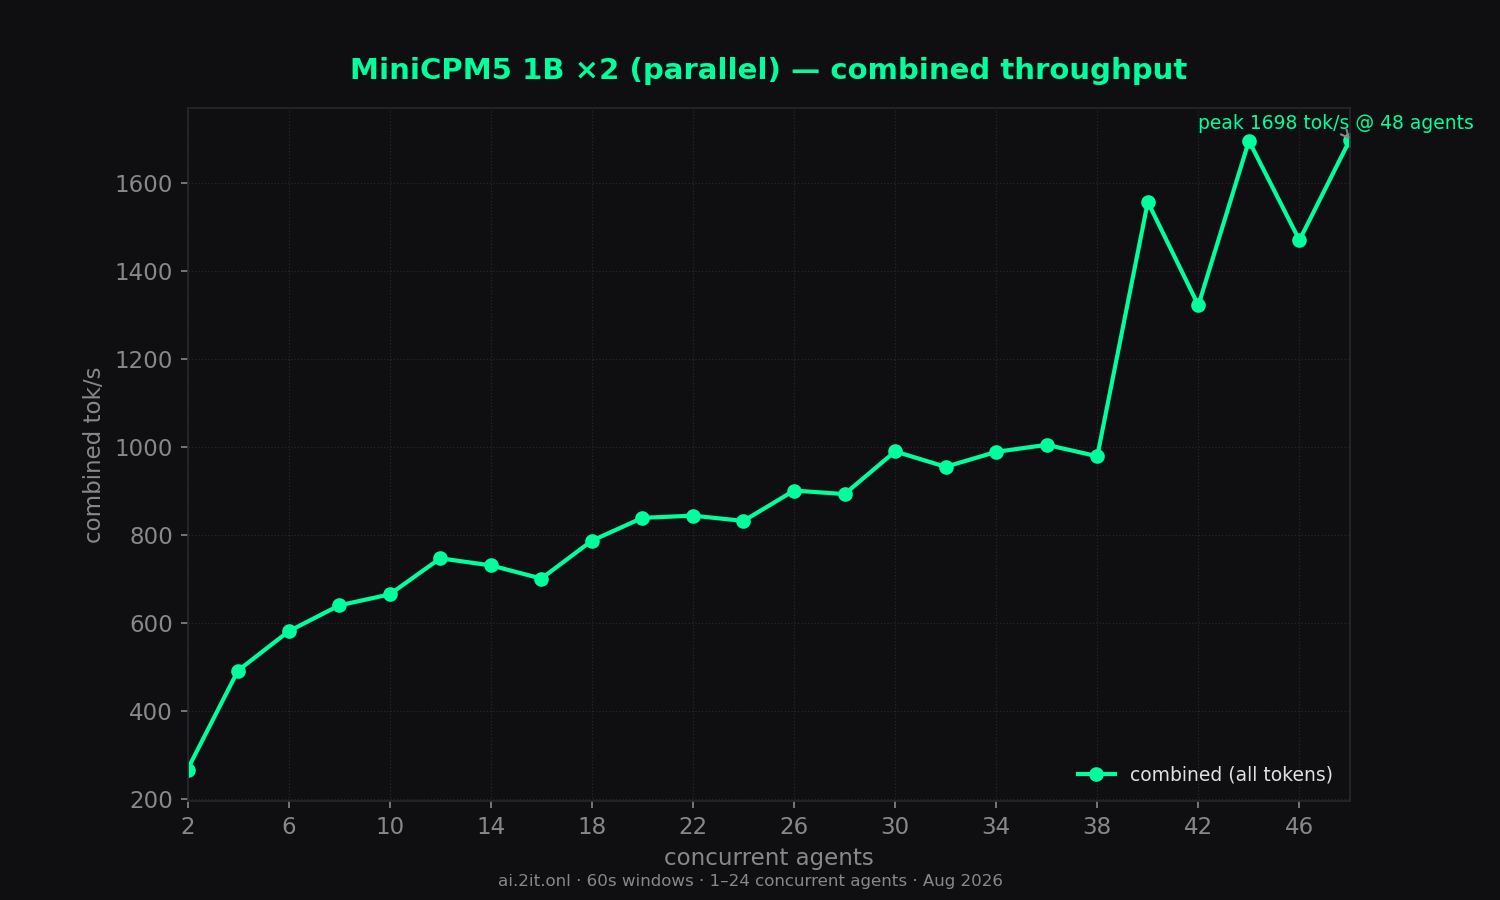
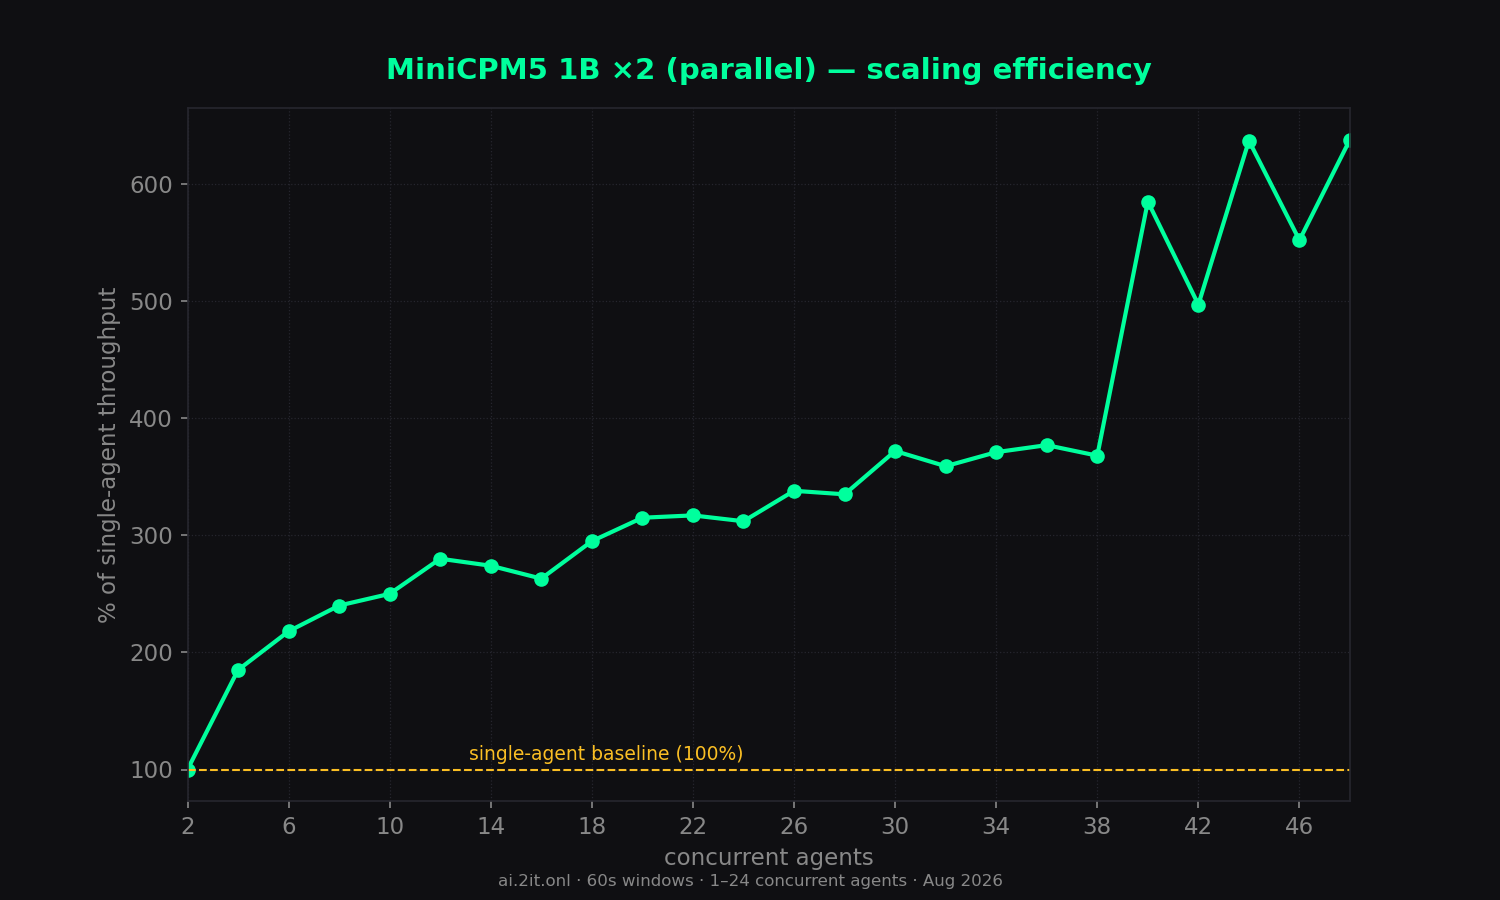
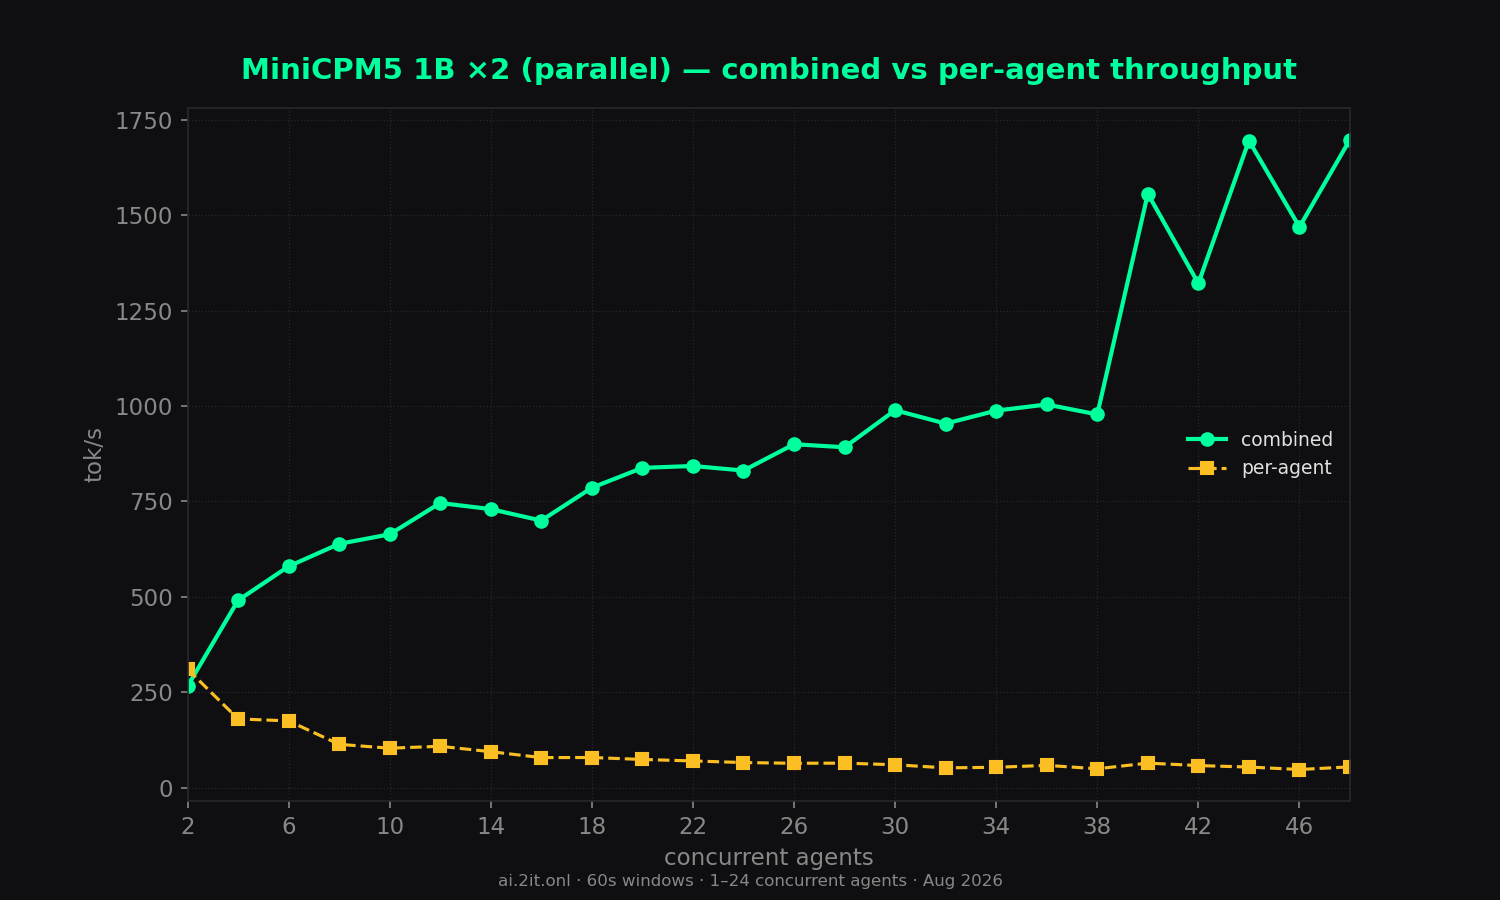
The thinking champion doubled: two parallel LM Studio instances — 843 tok/s inside the 24-agent window, up to 1,698 tok/s at 48 total agents (6.4x).
Key findings
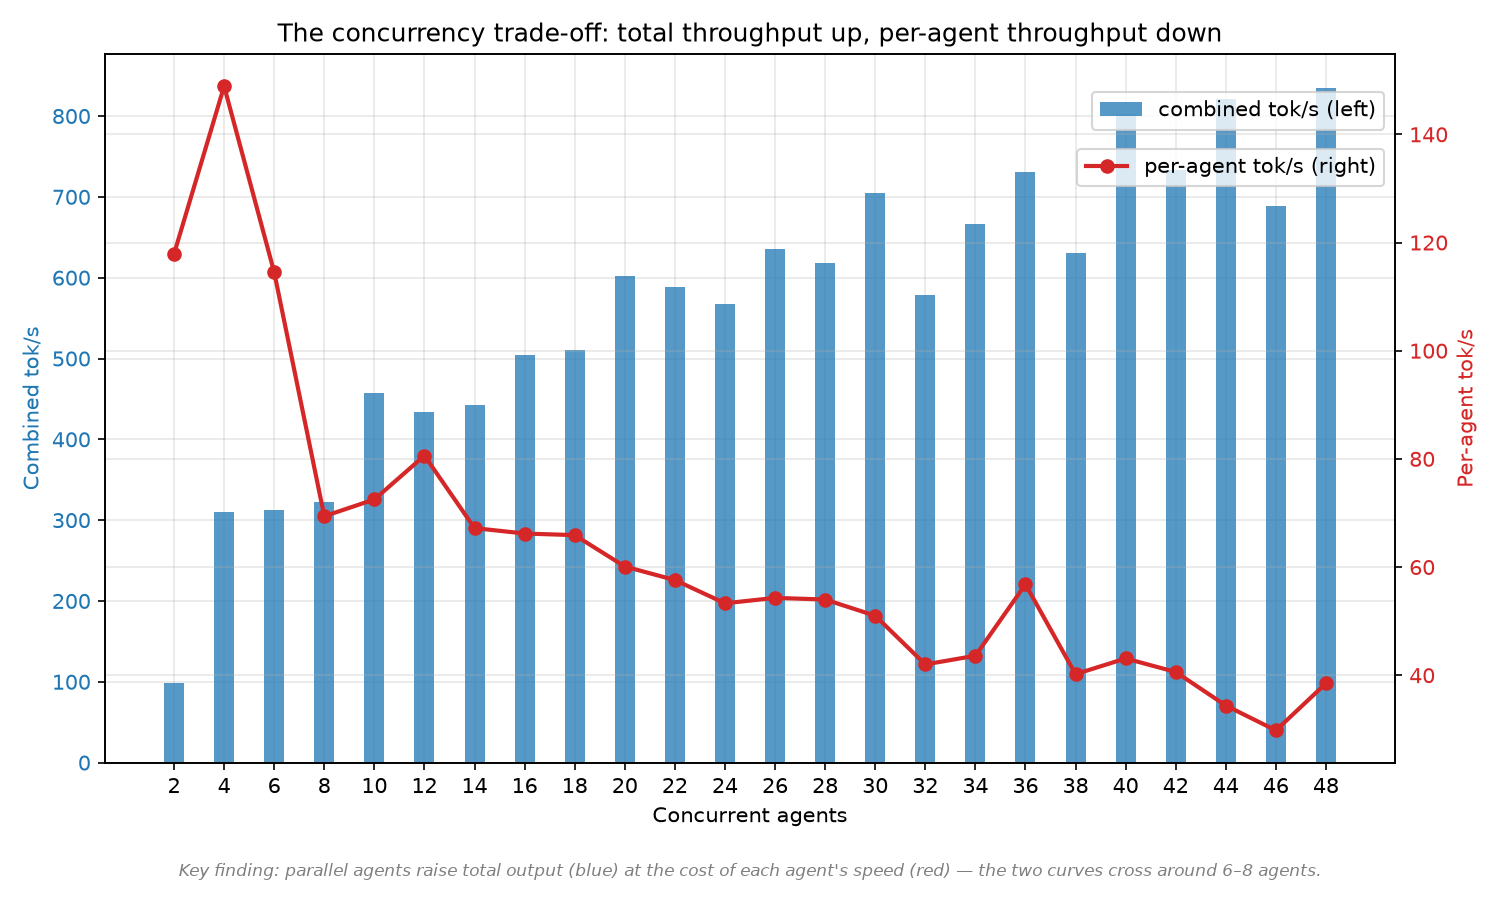
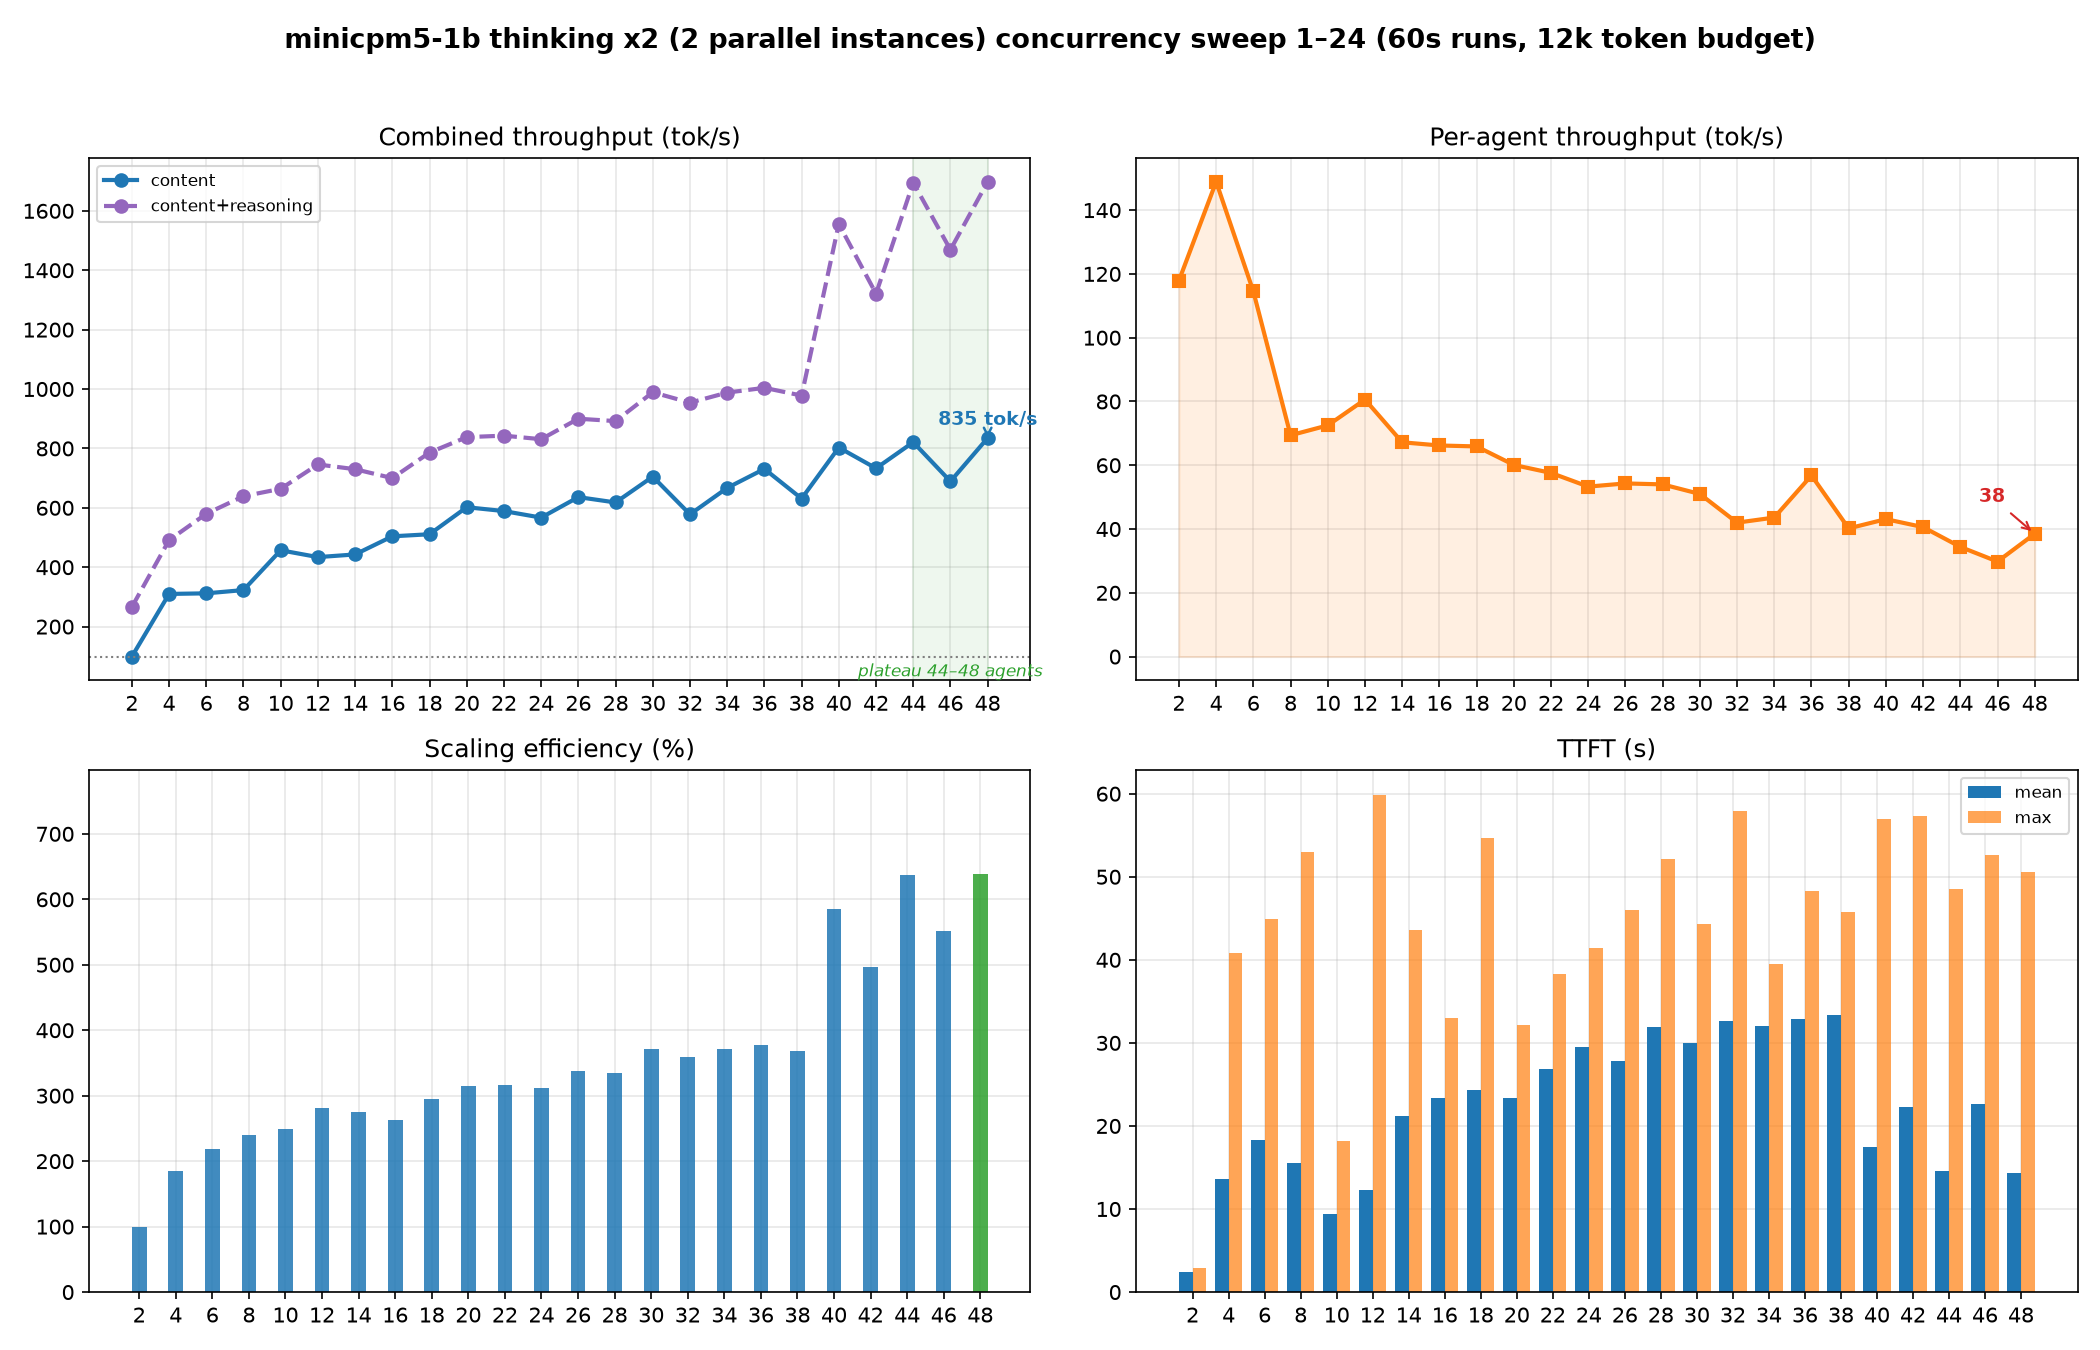
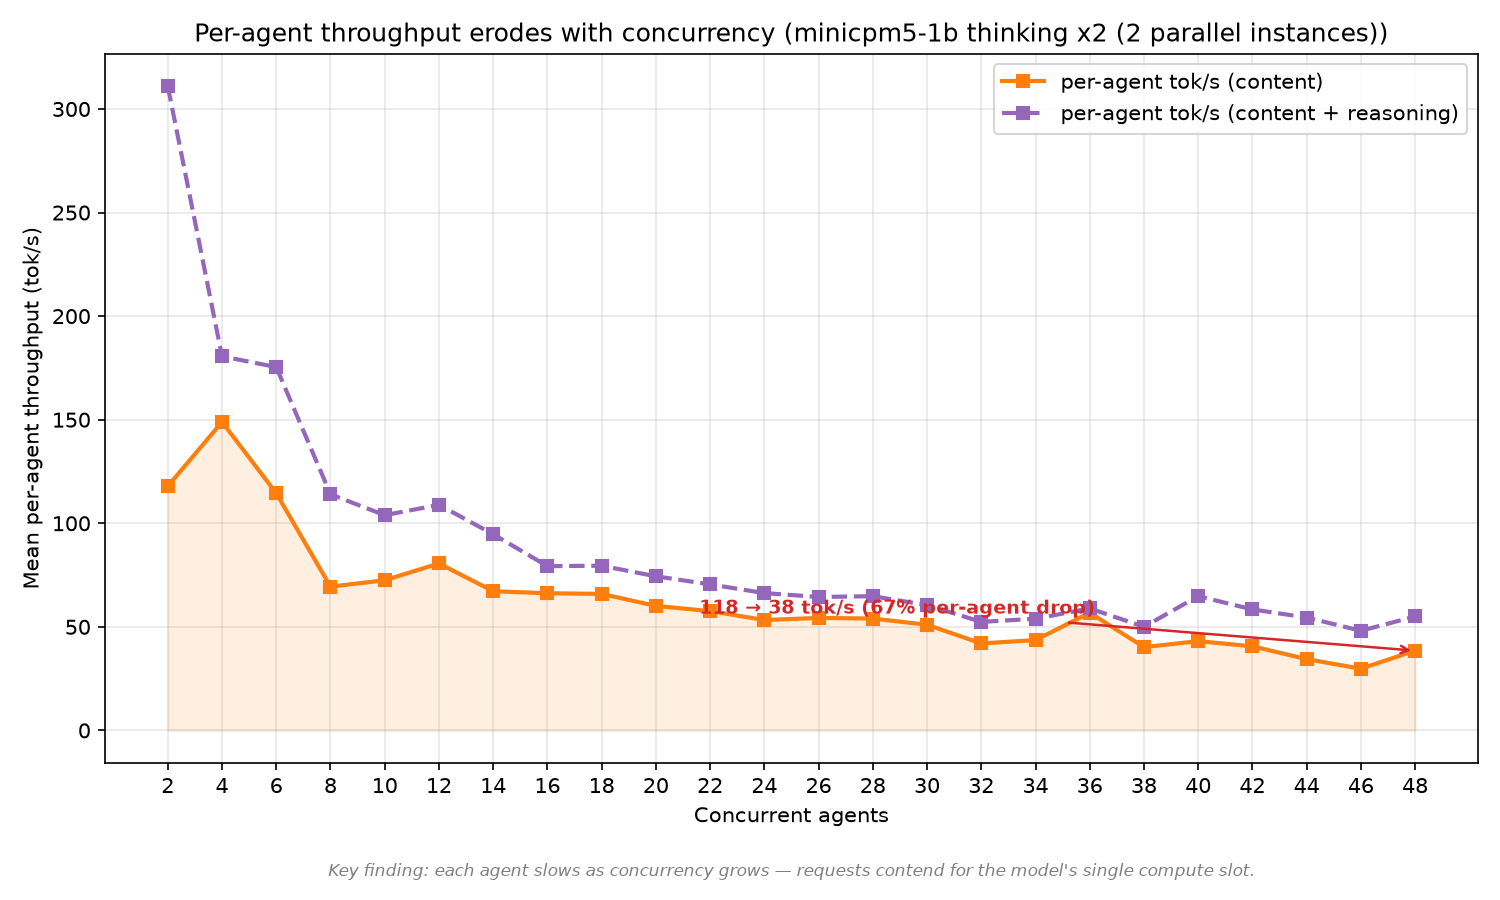
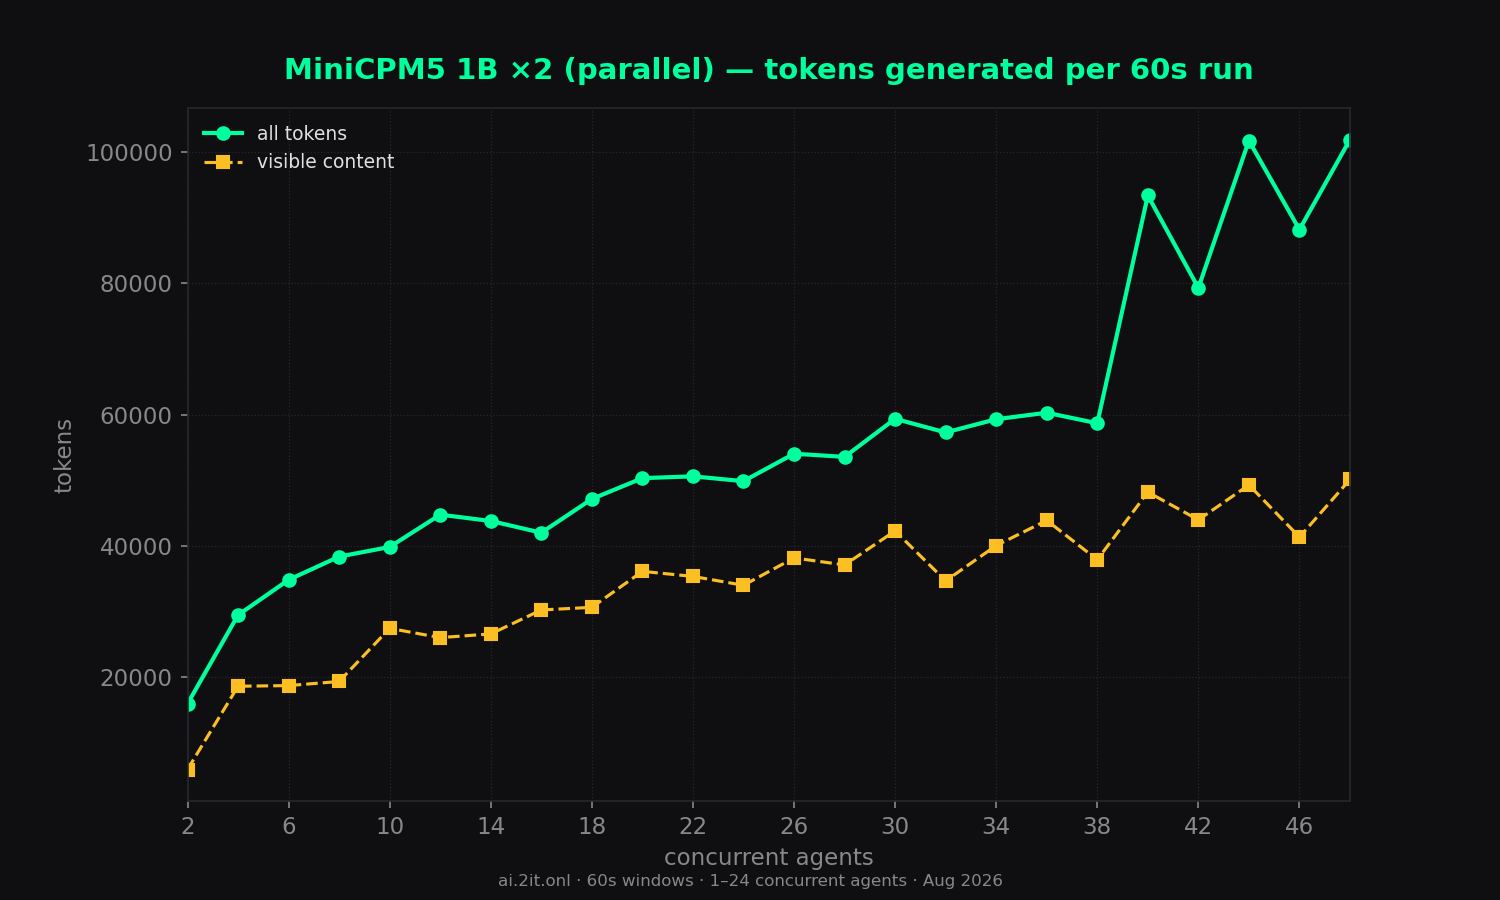
- Two instances roughly double throughput again: combined all-token output reaches 1698 tok/s at 48 total agents (6.4x the 2-agent baseline) — vs the single-instance minicpm peak of ~983 tok/s. Visible content throughput also tops out at 835 tok/s at 48, well above the single-instance ~537.
- Late-game jump: throughput holds ~830–1000 between 20–38 agents, then jumps to 1321–1698 at 40–48 — the two slots' batching kicks in hard at the top end.
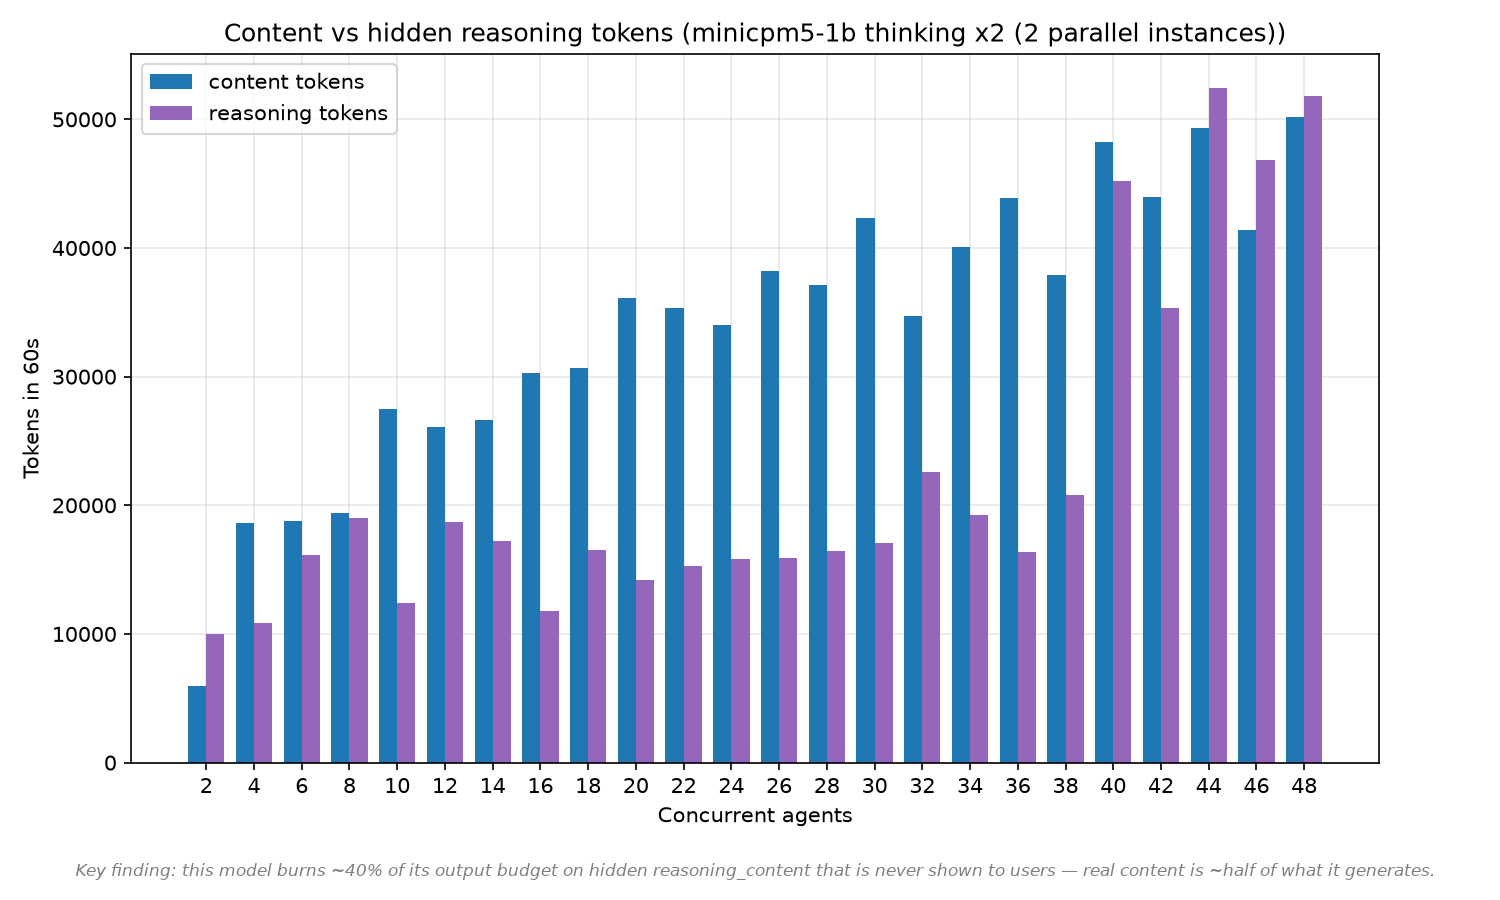
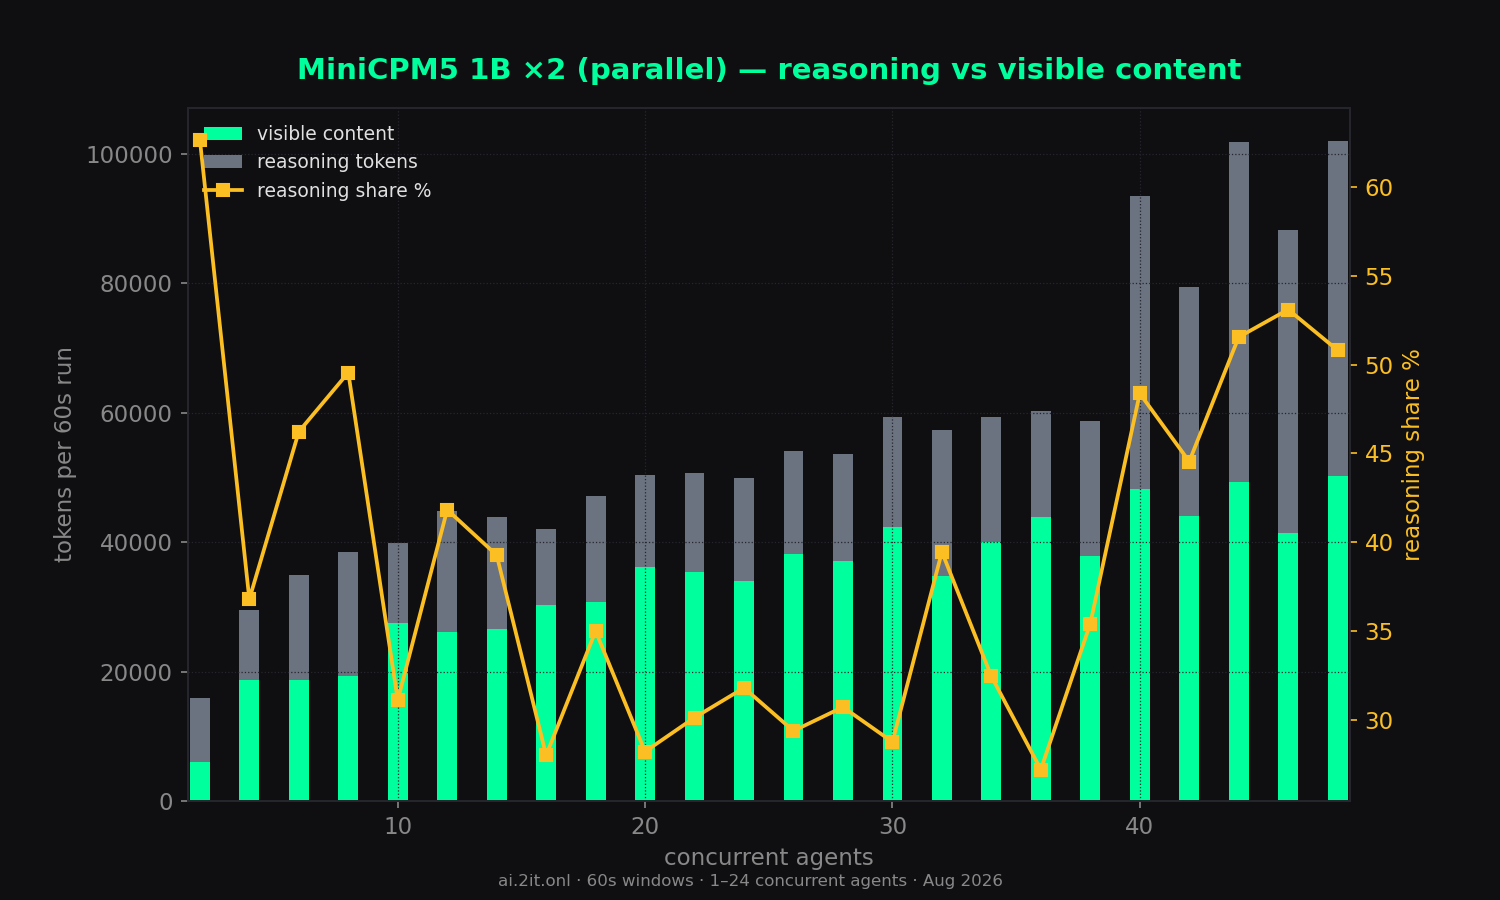
- Reasoning share climbs with load: ~63% of tokens at total-2, settling to ~25–55% in the mid-range, then back up to ~48–52% at 44–48.
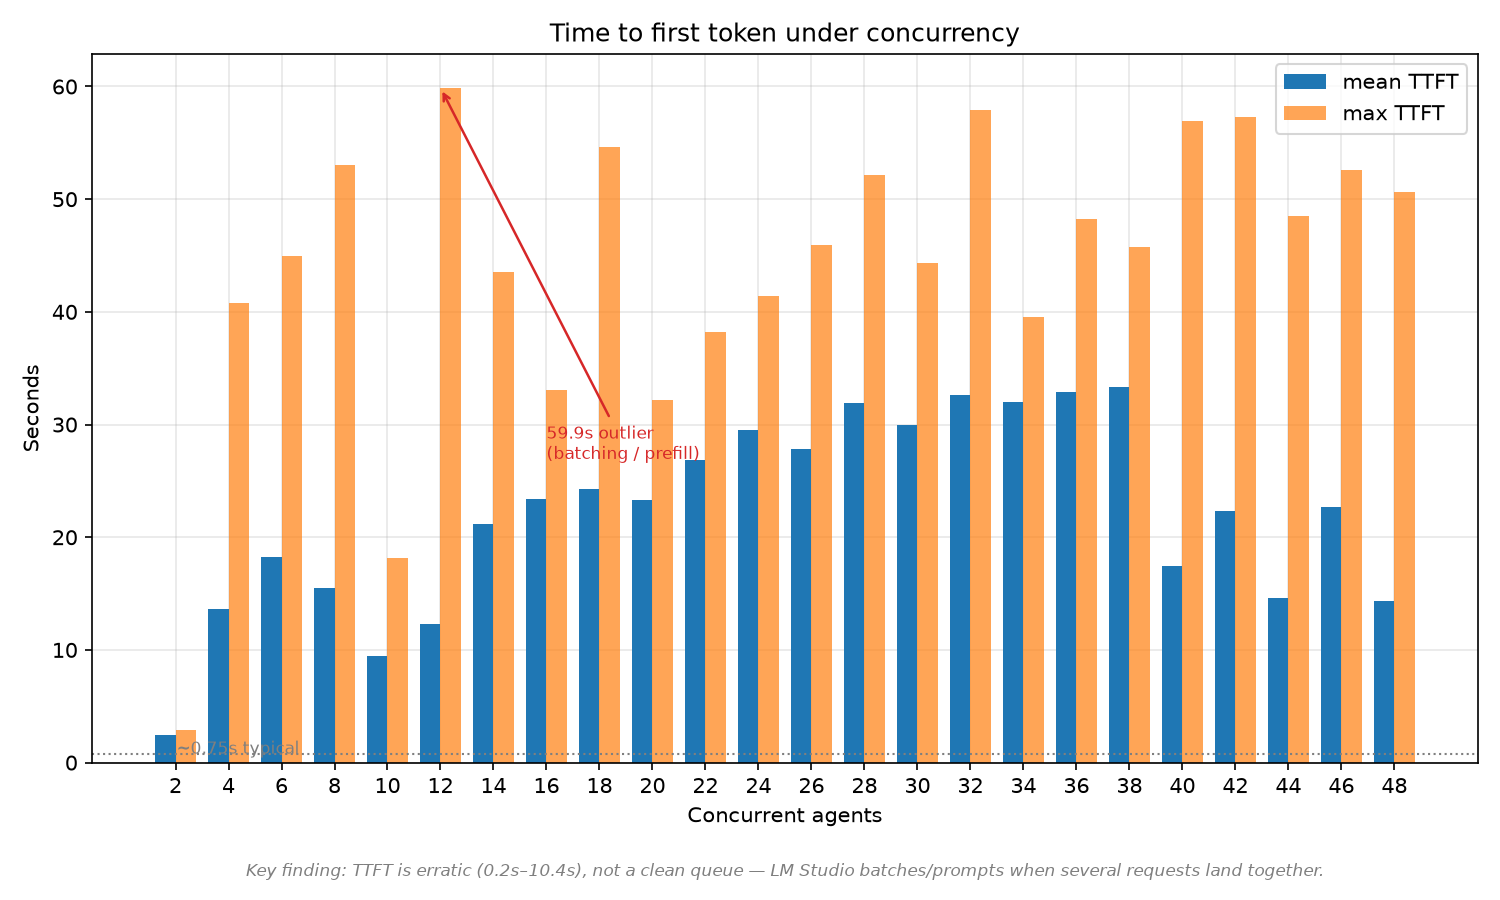
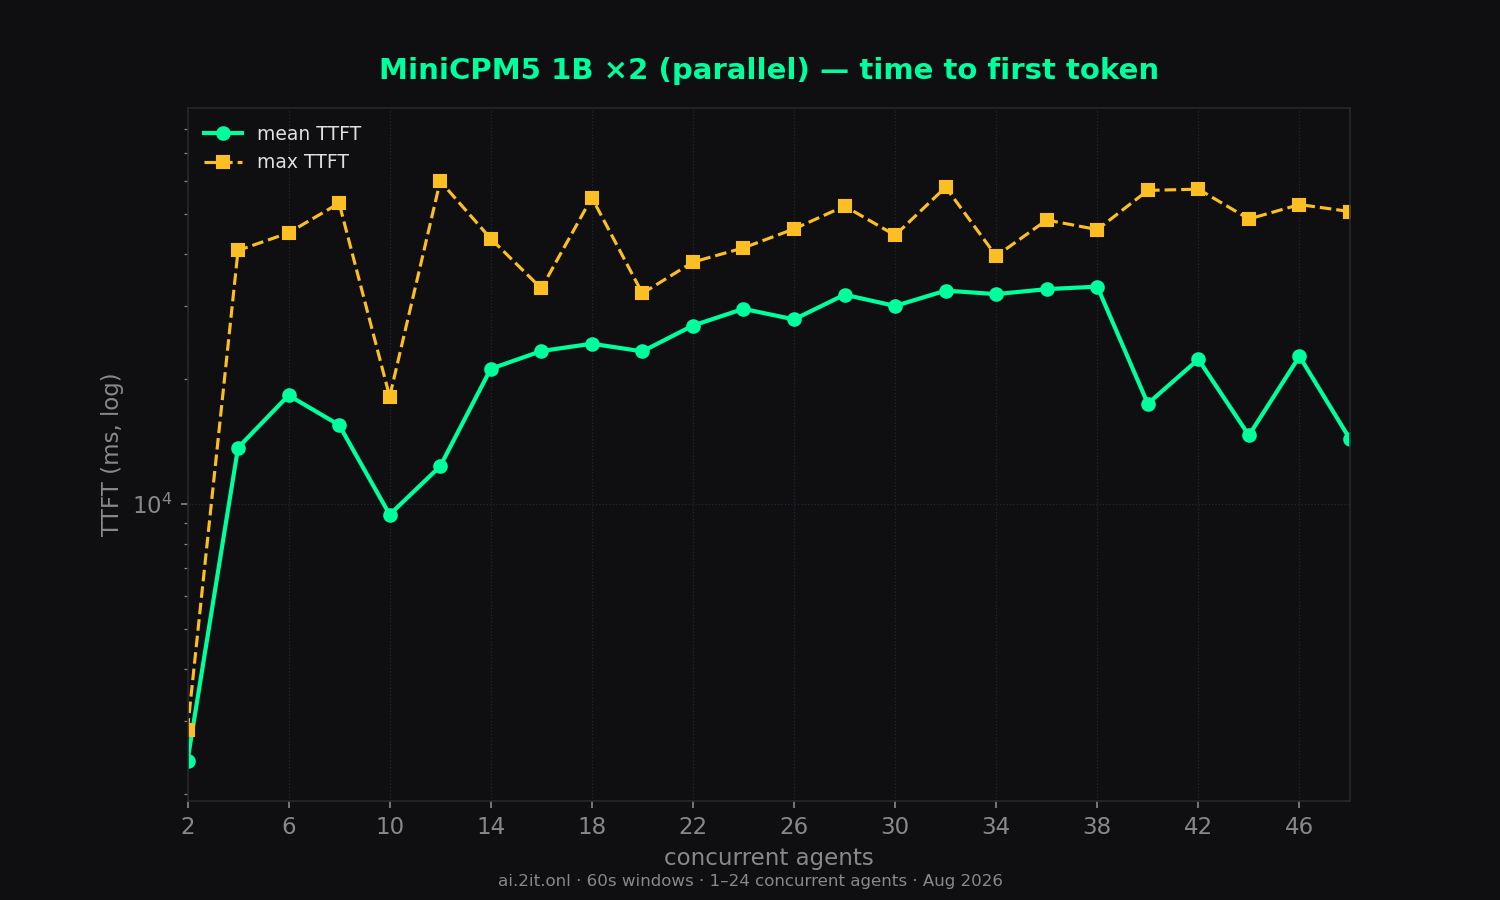
- TTFT is poor (thinking model): 2.4s at total-2, mostly 14–33s under load with max values up to 59.9s. Latency-critical use remains a bad fit.
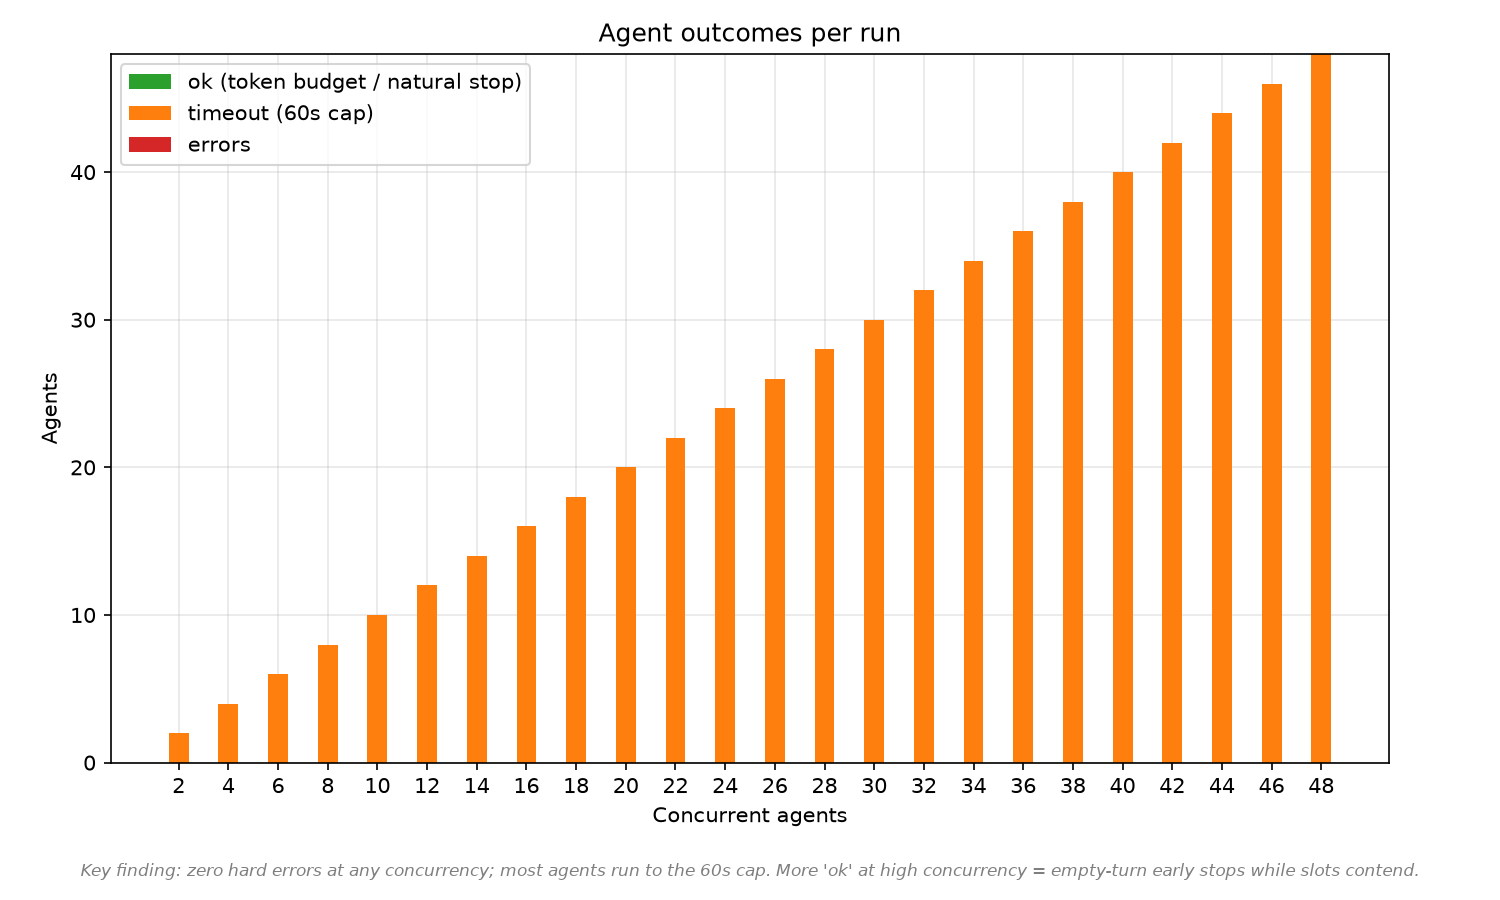
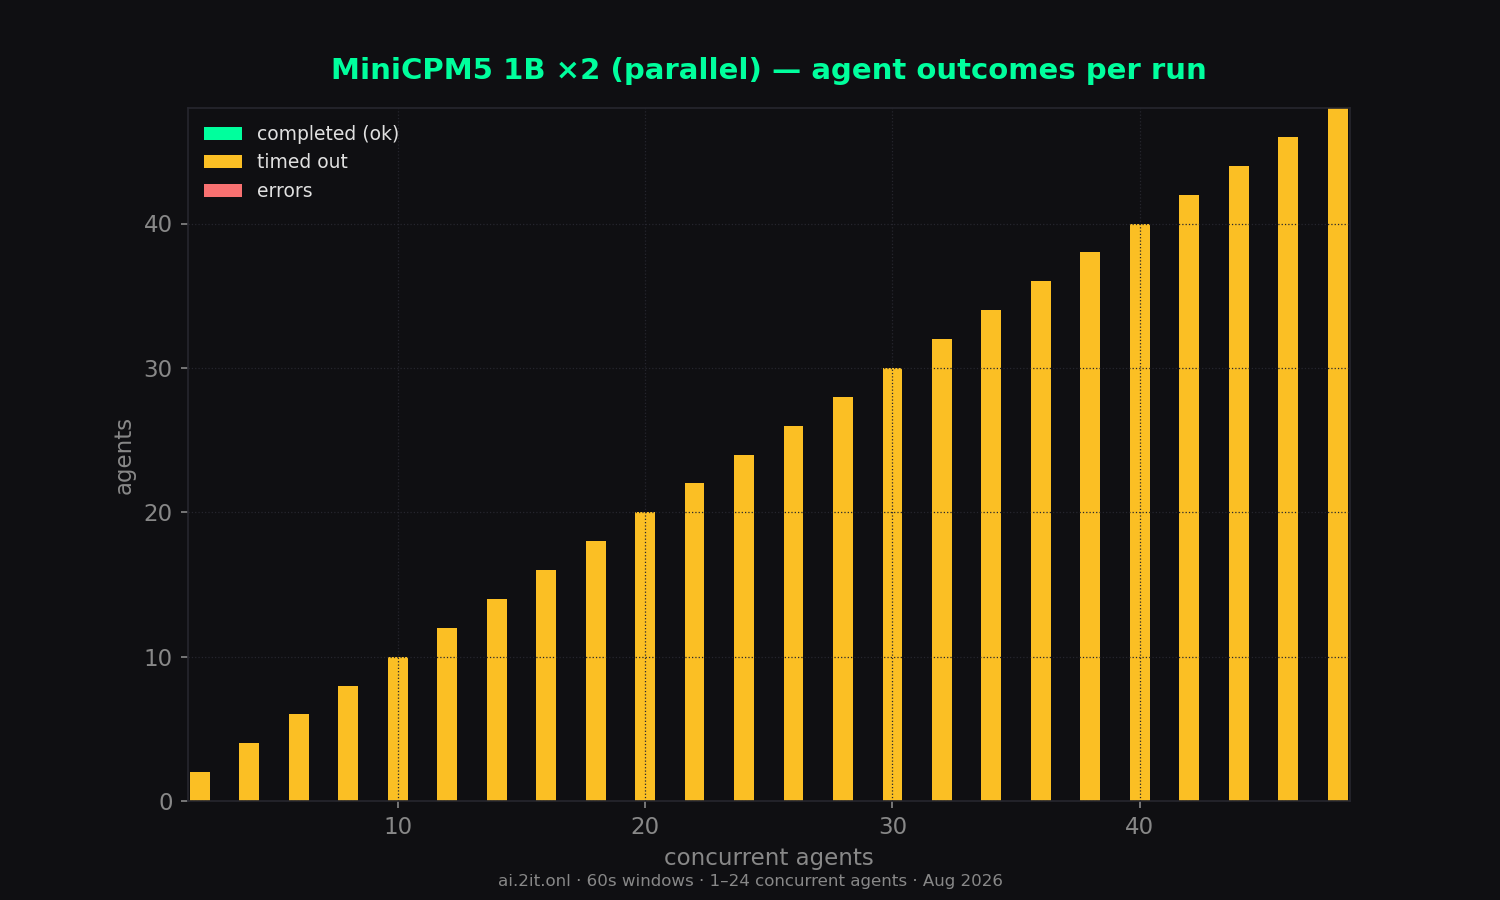
- Errors: 0 across all 24 levels.
Sweep — total concurrency 2–48
| agents | wall (s) | content | reason | total | comb tok/s | comb all | per-agent | per-agent all | scale % | TTFT mean | TTFT max | ok | timeout | err |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 2 | 60.0 | 5,957 | 10,003 | 15,960 | 99 | 266 | 117.9 | 311.0 | 100% | 2.4s | 2.9s | 0 | 2 | 0 |
| 4 | 60.0 | 18,640 | 10,849 | 29,489 | 310 | 491 | 148.9 | 180.6 | 185% | 13.7s | 40.8s | 0 | 4 | 0 |
| 6 | 60.0 | 18,742 | 16,109 | 34,851 | 312 | 580 | 114.5 | 175.4 | 218% | 18.3s | 45.0s | 0 | 6 | 0 |
| 8 | 60.0 | 19,367 | 19,022 | 38,389 | 323 | 639 | 69.4 | 114.0 | 240% | 15.5s | 53.0s | 0 | 8 | 0 |
| 10 | 60.0 | 27,462 | 12,396 | 39,858 | 457 | 664 | 72.5 | 103.9 | 250% | 9.4s | 18.1s | 0 | 10 | 0 |
| 12 | 60.0 | 26,050 | 18,731 | 44,781 | 434 | 746 | 80.6 | 108.9 | 280% | 12.3s | 59.9s | 0 | 12 | 0 |
| 14 | 60.0 | 26,611 | 17,207 | 43,818 | 443 | 730 | 67.2 | 94.7 | 274% | 21.2s | 43.5s | 0 | 14 | 0 |
| 16 | 60.0 | 30,262 | 11,768 | 42,030 | 504 | 700 | 66.2 | 79.3 | 263% | 23.4s | 33.0s | 0 | 16 | 0 |
| 18 | 60.0 | 30,662 | 16,506 | 47,168 | 511 | 786 | 65.9 | 79.5 | 295% | 24.3s | 54.7s | 0 | 18 | 0 |
| 20 | 60.0 | 36,144 | 14,200 | 50,344 | 602 | 838 | 60.1 | 74.4 | 315% | 23.3s | 32.2s | 0 | 20 | 0 |
| 22 | 60.0 | 35,373 | 15,247 | 50,620 | 589 | 843 | 57.6 | 70.5 | 317% | 26.9s | 38.2s | 0 | 22 | 0 |
| 24 | 60.0 | 34,024 | 15,861 | 49,885 | 567 | 831 | 53.3 | 66.3 | 312% | 29.5s | 41.4s | 0 | 24 | 0 |
| 26 | 60.0 | 38,187 | 15,880 | 54,067 | 636 | 900 | 54.3 | 64.4 | 338% | 27.8s | 45.9s | 0 | 26 | 0 |
| 28 | 60.0 | 37,126 | 16,458 | 53,584 | 618 | 892 | 54.0 | 64.8 | 335% | 31.9s | 52.2s | 0 | 28 | 0 |
| 30 | 60.0 | 42,308 | 17,074 | 59,382 | 705 | 989 | 51.0 | 60.5 | 372% | 30.0s | 44.4s | 0 | 30 | 0 |
| 32 | 60.0 | 34,699 | 22,610 | 57,309 | 578 | 954 | 42.0 | 52.4 | 359% | 32.6s | 57.9s | 0 | 32 | 0 |
| 34 | 60.1 | 40,074 | 19,247 | 59,321 | 667 | 988 | 43.6 | 53.9 | 371% | 32.0s | 39.5s | 0 | 34 | 0 |
| 36 | 60.0 | 43,907 | 16,403 | 60,310 | 731 | 1,004 | 56.8 | 58.9 | 377% | 32.9s | 48.3s | 0 | 36 | 0 |
| 38 | 60.0 | 37,917 | 20,791 | 58,708 | 631 | 978 | 40.2 | 50.0 | 368% | 33.4s | 45.8s | 0 | 38 | 0 |
| 40 | 60.0 | 48,223 | 45,189 | 93,412 | 803 | 1,556 | 43.1 | 64.8 | 585% | 17.4s | 56.9s | 0 | 40 | 0 |
| 42 | 60.0 | 43,992 | 35,332 | 79,324 | 733 | 1,321 | 40.6 | 58.4 | 497% | 22.3s | 57.3s | 0 | 42 | 0 |
| 44 | 60.1 | 49,306 | 52,456 | 101,762 | 821 | 1,695 | 34.4 | 54.5 | 637% | 14.6s | 48.6s | 0 | 44 | 0 |
| 46 | 60.0 | 41,365 | 46,836 | 88,201 | 689 | 1,469 | 29.8 | 48.1 | 552% | 22.7s | 52.6s | 0 | 46 | 0 |
| 48 peak | 60.1 | 50,144 | 51,793 | 101,937 | 835 | 1,698 | 38.5 | 55.0 | 638% | 14.3s | 50.6s | 0 | 48 | 0 |
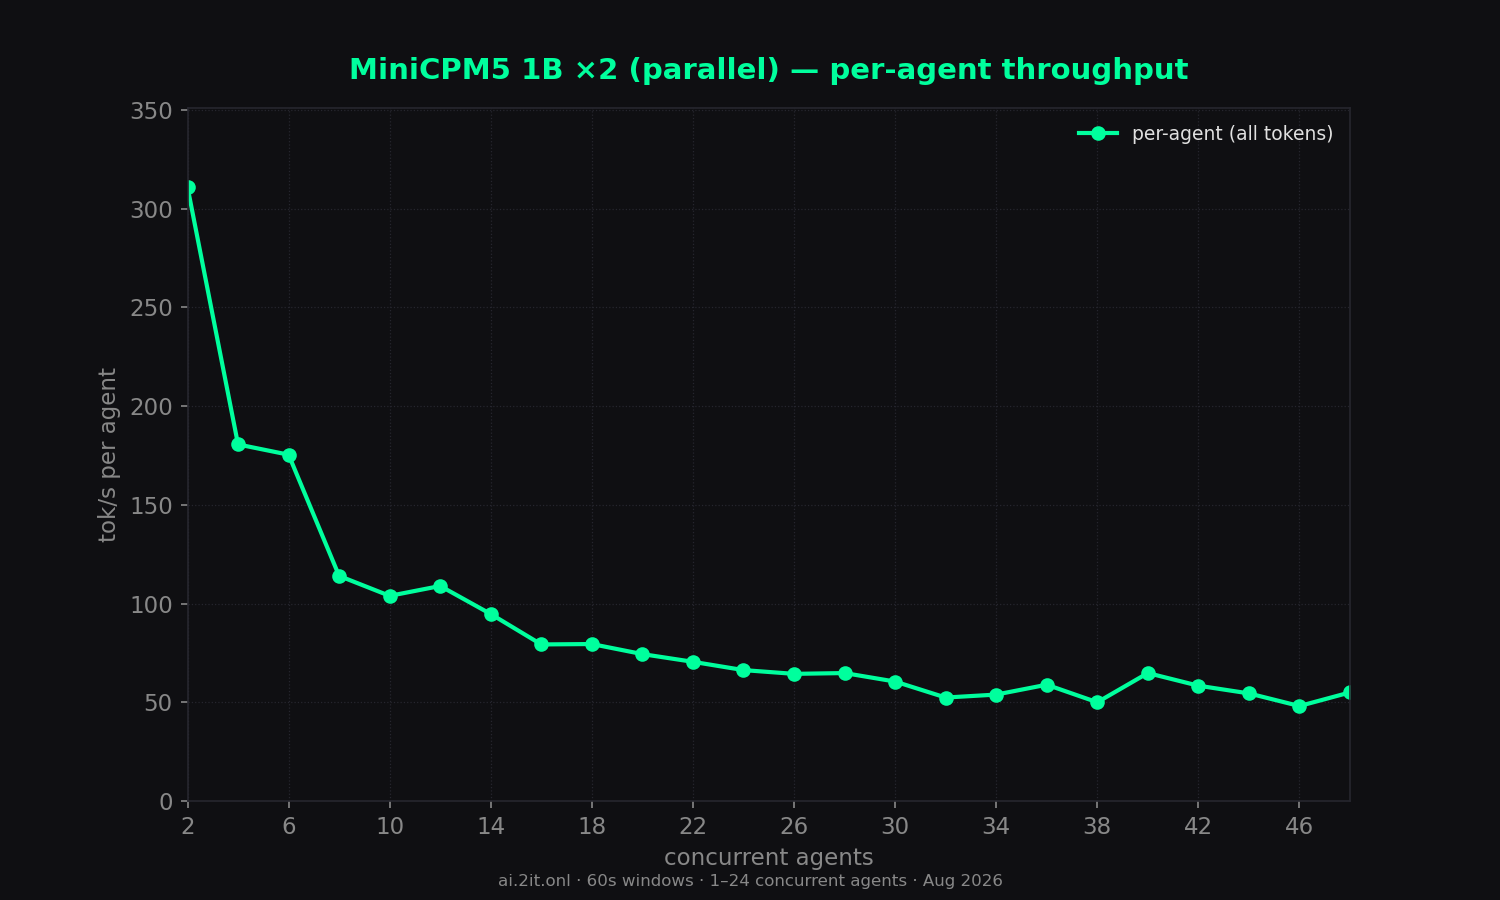
Parallel run: N agents ran on each of two LM Studio instances simultaneously (total 2×N). * burst artifact — agents queued ~11–16s then generated in a short burst; the per-agent timer inflates the number. Trust combined throughput and TTFT columns. Peak row = highest combined (all-token) throughput.
Charts
Raw data & downloads
- report.md6 KB
- sweep-summary.csv3 KB
- sweep-summary.json11 KB
- combined_throughput.png138 KB · original matplotlib export
- combined_vs_per_agent.png110 KB · original matplotlib export
- dashboard_1_24.png197 KB · original matplotlib export
- outcome_breakdown.png59 KB · original matplotlib export
- per_agent_throughput.png113 KB · original matplotlib export
- reasoning_vs_content.png64 KB · original matplotlib export
- scaling_efficiency.png86 KB · original matplotlib export
- time_to_first_token.png69 KB · original matplotlib export
- total_tokens_generated.png81 KB · original matplotlib export